A pose estimator you can train without a single real label.
Looking for a robust, general 6D pose estimator for RGB-D images from any sensor, for your own robotic setup? CPPF++ estimates the pose and size of everyday objects from a single RGB-D frame. It is trained only on synthetic CAD models, without real images, real pose labels or backgrounds, and still transfers to real scenes: a new voting mechanism keeps the model from overfitting to the training domain.
on NOCS REAL275 at 10°/5 cm, the best among methods trained on synthetic objects only (CPPF: 45.2).
for bowls on DiversePose 300 at 60°/5 cm, versus 66.2 for the best prior method.
used in training: only rendered CAD models, with no background or clutter.
What makes it work
Sim2Real by design
The only prior knowledge is a set of 3D CAD models. Training data is rendered online from these objects alone, so there is no dependence on real annotations, backgrounds or a particular camera.
Uncertainty-aware voting
Point pairs with similar local geometry can point to very different places on an object, a problem we call vote collision. CPPF++ predicts a probability distribution for each vote in canonical space instead of a single guess.
N-point tuples
Voting units of N points instead of pairs carry more context. Two pairs that look identical become distinguishable once a third point is added.
Filtering and refinement
Noisy tuples are filtered out before they vote on orientation, an online alignment step refines rotation and translation, and a tuple feature ensemble adds robustness.
Pipeline
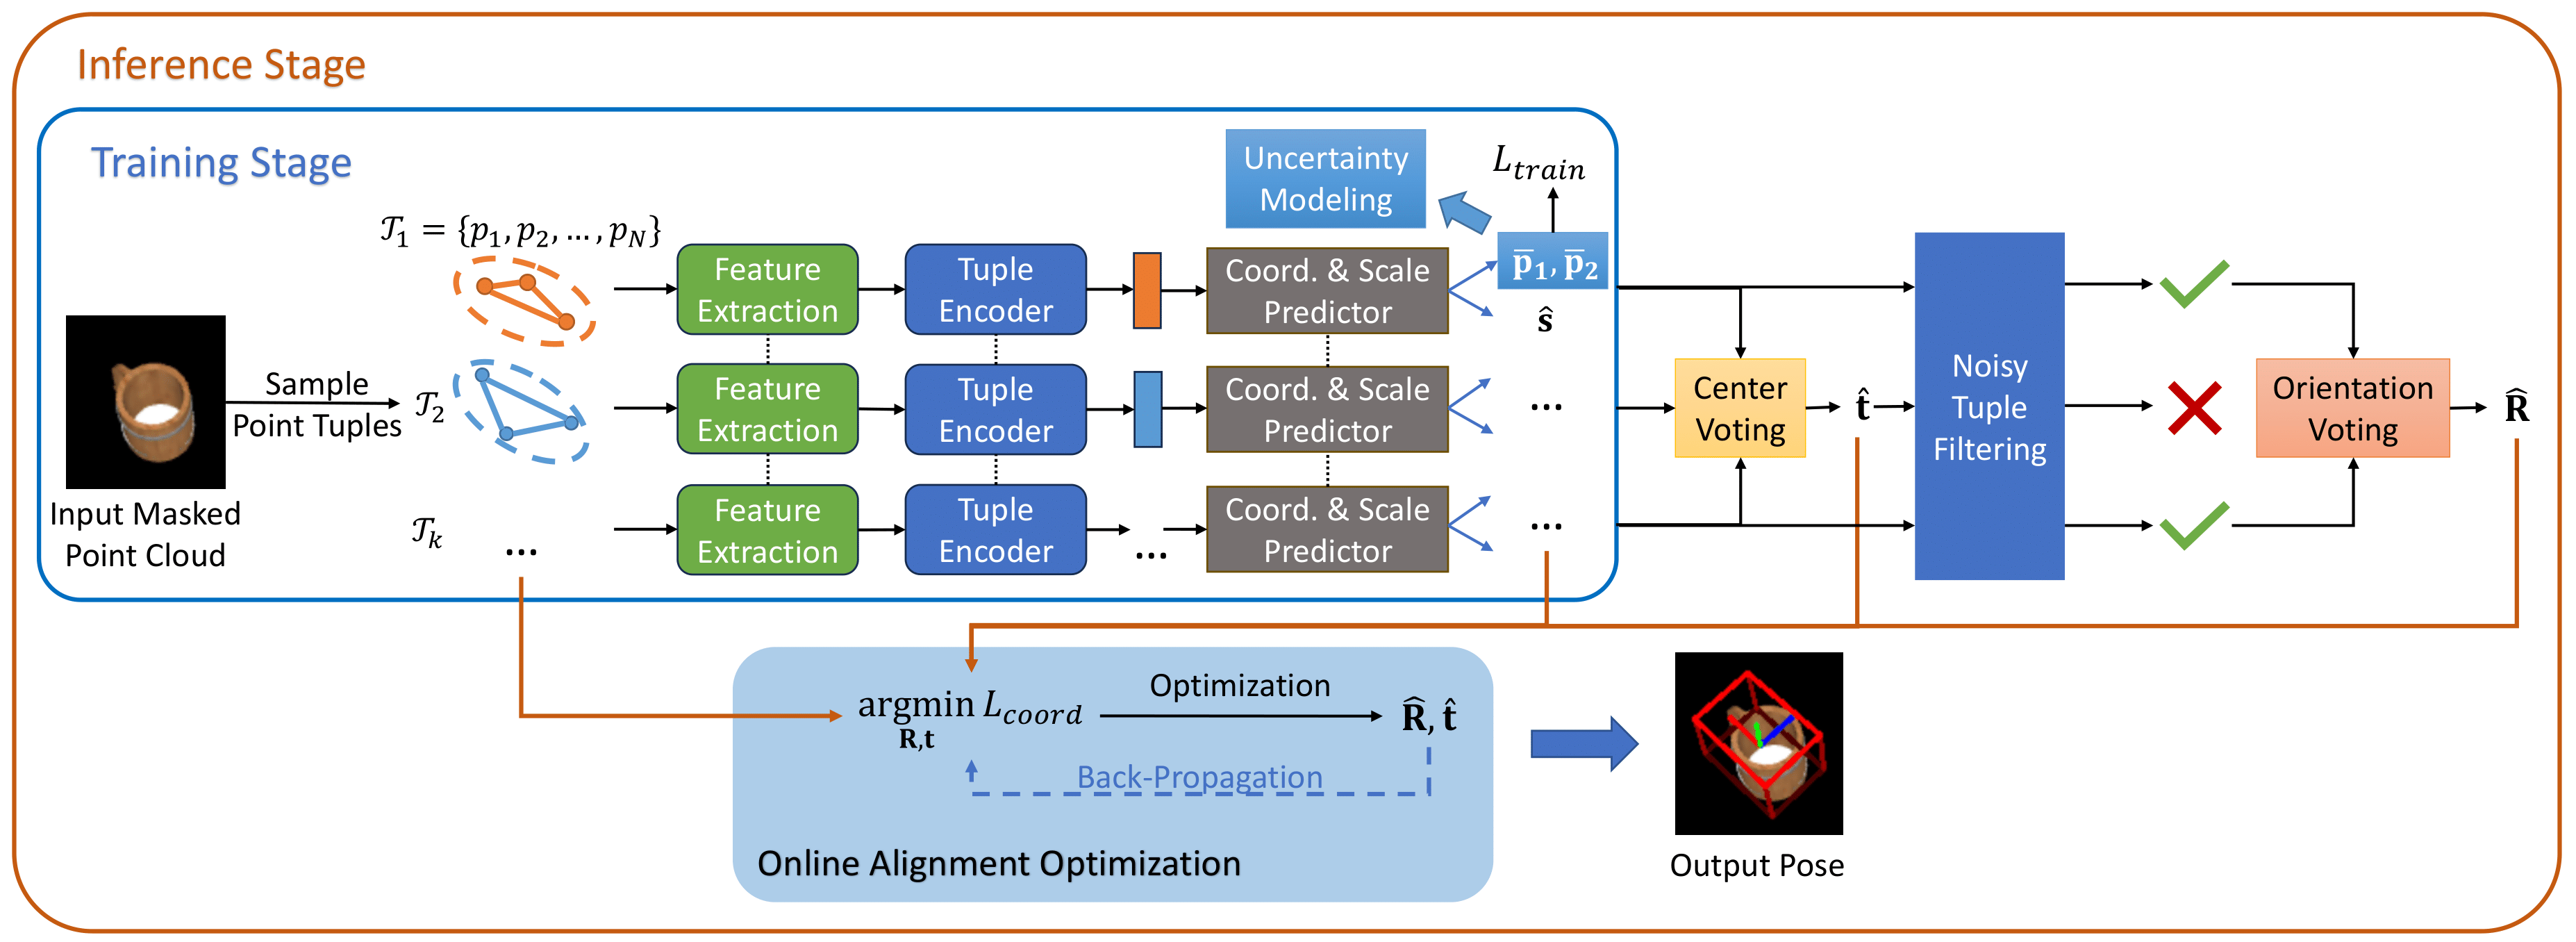
- Masked inputA masked point cloud from an off-the-shelf instance segmentation model.
- Point tuplesTuples are randomly sampled from the object and encoded into tuple embeddings.
- Coordinates & scaleEach tuple predicts its canonical coordinates and scale, with uncertainty.
- VotingTuples vote for the centre; only reliable tuples vote for the orientation.
- Online alignmentAn optimization step refines the predicted rotation and translation.
A casual iPhone 15 video, straight from the model.
The pose of the mug is estimated independently on every frame of a handheld clip.
- No temporal smoothing
- No object mesh required
- Trained on synthetic data only
CPPF++ also serves as the pose module of RPMArt (IROS 2024) for articulated objects such as microwaves and drawers.
Strong on REAL275, stronger in new domains
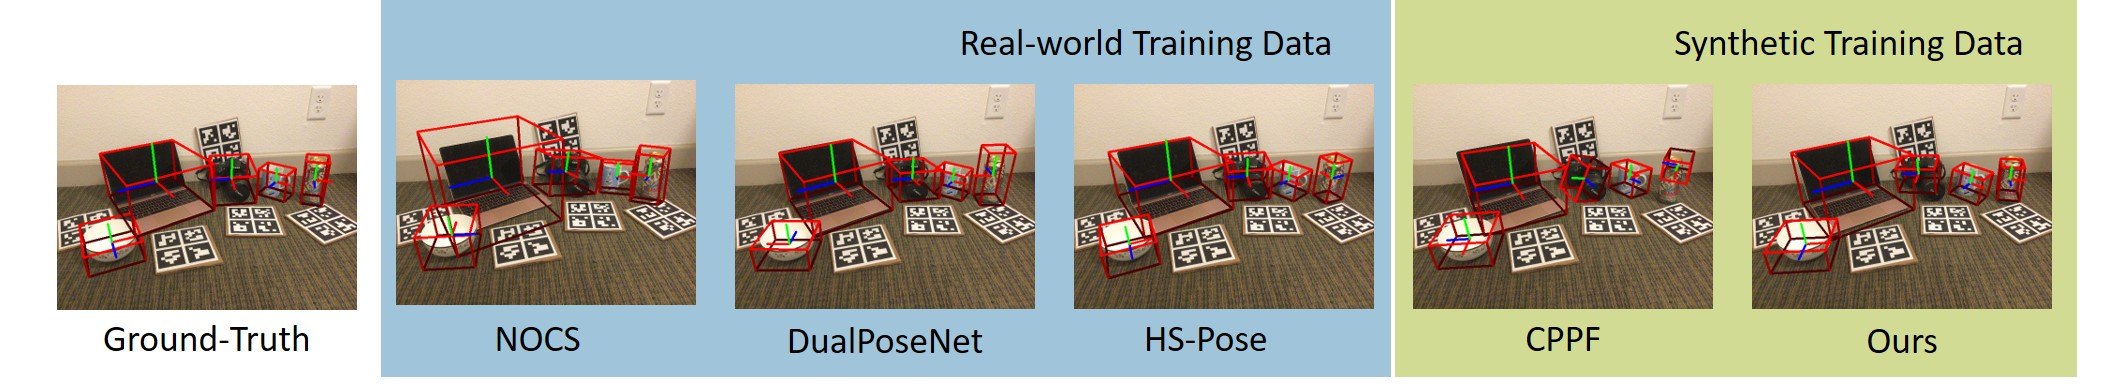
On NOCS REAL275, CPPF++ is the best method trained on synthetic objects only, and is comparable to methods trained with real pose labels. When transferred to new data domains (Wild6D, PhoCAL and DiversePose 300), it generalizes better than previous methods. Pick a benchmark and a category below.
| Method | Training data | 3D25 | 3D50 | 5° 5 cm | 10° 5 cm | 15° 5 cm |
|---|---|---|---|---|---|---|
| NOCS | Syn. Obj + Real Obj & BG | 74.4 | 27.8 | 9.8 | 24.1 | 34.9 |
| CASS | Syn. Obj + Real Obj & BG | – | – | 23.5 | 58.0 | – |
| SPD | Syn. Obj + Real Obj & BG | – | – | 21.4 | 54.1 | – |
| FS-Net | Syn. Obj + Real Obj & BG | – | – | 28.2 | 60.8 | – |
| CenterSnap | Syn. Obj + Real Obj & BG | – | – | 27.2 | 58.8 | – |
| ShAPO | Syn. Obj + Real Obj & BG | – | – | 48.8 | 66.8 | – |
| DualPoseNet | Syn. Obj + Real Obj & BG | 82.3 | 57.3 | 36.1 | 67.8 | 76.3 |
| HS-Pose | Syn. Obj + Real Obj & BG | 82.6 | 71.6 | 56.1 | 84.1 | 92.8 |
| RePoNet | Syn. Obj + Real Obj & BG (w/o label) | – | – | 33.9 | 63.0 | – |
| UDA-COPE | Syn. Obj + Real Obj & BG (w/o label) | – | – | 34.8 | 66.0 | – |
| TTA-COPE | Syn. Obj + Real Obj & BG (w/o label) | – | – | 35.9 | 73.2 | – |
| SAR-Net | Syn. Obj + Real BG | 77.9 | 47.5 | 42.3 | 68.3 | 75.0 |
| Chen et al. | Syn. Obj | 16.7 | 0.7 | 0.8 | 3.1 | 7.2 |
| Gao et al. | Syn. Obj | 70.6 | 23.1 | 5.1 | 14.2 | 21.9 |
| SAR-Net* | Syn. Obj | 64.0 | 34.0 | 4.8 | 21.1 | 30.7 |
| CPPF | Syn. Obj | 78.2 | 25.0 | 18.0 | 45.2 | 51.6 |
| CPPF++ (ours) | Syn. Obj | 82.4 | 55.2 | 32.3 | 65.9 | 85.2 |
| CPPF++ (ours) w/ GroundedSAM Det. | Syn. Obj | 72.7 | 58.0 | 26.2 | 72.0 | 88.9 |
| Method | 3D25 | 3D50 | 5° 5 cm | 10° 5 cm | 15° 5 cm |
|---|---|---|---|---|---|
| NOCS | 42.1 | 15.1 | 2.7 | 12.9 | 28.7 |
| DualPoseNet | 50.2 | 25.8 | 38.2 | 84.9 | 97.5 |
| HS-Pose | 46.8 | 37.3 | 53.3 | 96.9 | 99.8 |
| SAR-Net* | 28.6 | 6.8 | 11.6 | 42.6 | 61.3 |
| CPPF | 28.6 | 0.2 | 26.7 | 85.7 | 94.4 |
| CPPF++ (ours) | 48.1 | 22.4 | 42.6 | 96.9 | 99.4 |
| Method | 3D25 | 3D50 | 5° 5 cm | 10° 5 cm | 15° 5 cm |
|---|---|---|---|---|---|
| NOCS | 100.0 | 88.6 | 49.7 | 84.3 | 96.4 |
| DualPoseNet | 100.0 | 97.3 | 78.8 | 97.5 | 99.7 |
| HS-Pose | 99.7 | 99.7 | 92.4 | 99.6 | 99.8 |
| SAR-Net* | 99.6 | 23.1 | 11.6 | 60.4 | 81.9 |
| CPPF | 96.8 | 7.1 | 7.7 | 40.1 | 62.9 |
| CPPF++ (ours) | 100.0 | 81.0 | 48.5 | 75.8 | 93.3 |
| Method | 3D25 | 3D50 | 5° 5 cm | 10° 5 cm | 15° 5 cm |
|---|---|---|---|---|---|
| NOCS | 79.4 | 13.1 | 0.0 | 0.1 | 0.6 |
| DualPoseNet | 90.0 | 33.3 | 0.0 | 0.5 | 3.7 |
| HS-Pose | 88.4 | 52.9 | 5.9 | 40.8 | 70.9 |
| SAR-Net* | 60.7 | 0.5 | 0.0 | 0.0 | 0.0 |
| CPPF | 88.3 | 4.2 | 0.0 | 0.0 | 0.0 |
| CPPF++ (ours) | 89.7 | 39.8 | 0.4 | 13.4 | 48.8 |
| Method | 3D25 | 3D50 | 5° 5 cm | 10° 5 cm | 15° 5 cm |
|---|---|---|---|---|---|
| NOCS | 39.0 | 6.7 | 0.4 | 7.9 | 18.0 |
| DualPoseNet | 70.2 | 20.9 | 47.0 | 93.0 | 97.7 |
| HS-Pose | 73.7 | 70.0 | 70.6 | 99.4 | 99.5 |
| SAR-Net* | 31.3 | 11.8 | 9.4 | 39.7 | 62.5 |
| CPPF | 73.9 | 34.7 | 45.5 | 95.4 | 97.7 |
| CPPF++ (ours) | 70.8 | 12.1 | 26.7 | 78.3 | 94.1 |
| Method | 3D25 | 3D50 | 5° 5 cm | 10° 5 cm | 15° 5 cm |
|---|---|---|---|---|---|
| NOCS | 92.8 | 0.6 | 6.5 | 41.2 | 68.2 |
| DualPoseNet | 84.8 | 82.5 | 49.2 | 88.7 | 95.4 |
| HS-Pose | 86.3 | 80.9 | 78.7 | 92.2 | 92.7 |
| SAR-Net* | 82.9 | 26.9 | 0.0 | 0.0 | 0.0 |
| CPPF | 84.2 | 24.4 | 27.8 | 47.8 | 49.4 |
| CPPF++ (ours) | 85.9 | 80.9 | 71.8 | 87.3 | 95.7 |
| Method | 3D25 | 3D50 | 5° 5 cm | 10° 5 cm | 15° 5 cm |
|---|---|---|---|---|---|
| NOCS | 93.6 | 42.8 | 0.0 | 0.1 | 1.9 |
| DualPoseNet | 99.6 | 85.1 | 7.1 | 47.9 | 68.7 |
| HS-Pose | 97.7 | 90.8 | 24.6 | 77.6 | 86.2 |
| SAR-Net* | 62.4 | 0.0 | 0.0 | 0.6 | 2.4 |
| CPPF | 97.6 | 79.6 | 0.1 | 2.0 | 5.0 |
| CPPF++ (ours) | 99.6 | 95.3 | 3.8 | 43.8 | 80.1 |
NOCS REAL275. In the per-category tables, NOCS, DualPoseNet and HS-Pose are trained with real-world pose annotations, while SAR-Net*, CPPF and CPPF++ are pure sim-to-real methods. Bold: best, underlined: second best, as marked in the paper.
| Method | 3D25 | 3D50 | 5° 5 cm | 10° 5 cm | 15° 5 cm |
|---|---|---|---|---|---|
| NOCS | 50.5 | 34.1 | 39.2 | 82.4 | 91.2 |
| DualPoseNet | 89.5 | 61.7 | 43.2 | 80.1 | 92.1 |
| SAR-Net | 86.1 | 28.5 | 5.8 | 44.0 | 82.4 |
| RePoNet | 88.4 | 76.3 | 79.2 | 93.9 | 95.7 |
| HS-Pose | 87.1 | 70.4 | 54.3 | 89.1 | 94.1 |
| CPPF | 74.9 | 10.3 | 22.4 | 44.2 | 46.4 |
| CPPF++ (ours) | 81.9 | 51.9 | 49.7 | 94.8 | 97.2 |
| Method | 3D25 | 3D50 | 5° 5 cm | 10° 5 cm | 15° 5 cm |
|---|---|---|---|---|---|
| NOCS | 80.3 | 47.3 | 22.8 | 76.9 | 90.1 |
| DualPoseNet | 98.1 | 89.2 | 67.0 | 89.9 | 93.4 |
| SAR-Net | 93.0 | 0.5 | 38.1 | 83.2 | 92.4 |
| RePoNet | 97.3 | 86.2 | 71.2 | 91.2 | 92.9 |
| HS-Pose | 96.5 | 82.3 | 74.0 | 89.4 | 92.0 |
| CPPF | 91.2 | 14.3 | 11.8 | 35.2 | 49.2 |
| CPPF++ (ours) | 96.1 | 75.1 | 86.1 | 94.4 | 95.2 |
| Method | 3D25 | 3D50 | 5° 5 cm | 10° 5 cm | 15° 5 cm |
|---|---|---|---|---|---|
| NOCS | 10.4 | 1.7 | 0.0 | 0.0 | 0.0 |
| DualPoseNet | 82.5 | 22.0 | 0.0 | 1.2 | 3.9 |
| SAR-Net | 34.8 | 0.2 | 0.0 | 0.0 | 0.2 |
| RePoNet | 44.8 | 2.4 | 0.1 | 0.6 | 1.5 |
| HS-Pose | 59.8 | 5.4 | 0.0 | 0.3 | 1.1 |
| CPPF | 53.4 | 0.1 | 0.0 | 0.0 | 0.0 |
| CPPF++ (ours) | 63.0 | 15.7 | 0.7 | 9.2 | 15.8 |
| Method | 3D25 | 3D50 | 5° 5 cm | 10° 5 cm | 15° 5 cm |
|---|---|---|---|---|---|
| NOCS | 97.1 | 77.1 | 4.3 | 15.0 | 15.9 |
| DualPoseNet | 98.1 | 97.2 | 12.0 | 14.8 | 15.0 |
| SAR-Net | 95.7 | 1.1 | 0.0 | 0.0 | 0.0 |
| RePoNet | 97.3 | 93.1 | 14.5 | 18.0 | 19.4 |
| HS-Pose | 99.7 | 90.0 | 12.6 | 17.0 | 17.1 |
| CPPF | 95.5 | 36.3 | 4.6 | 10.2 | 11.0 |
| CPPF++ (ours) | 99.5 | 99.2 | 13.2 | 18.1 | 18.1 |
| Method | 3D25 | 3D50 | 5° 5 cm | 10° 5 cm | 15° 5 cm |
|---|---|---|---|---|---|
| NOCS | 16.5 | 0.4 | 0.0 | 0.2 | 1.0 |
| DualPoseNet | 82.5 | 63.5 | 0.5 | 3.3 | 5.3 |
| SAR-Net | 78.3 | 0.0 | 0.0 | 0.6 | 2.9 |
| RePoNet | 77.9 | 52.0 | 2.5 | 15.1 | 23.0 |
| HS-Pose | 83.8 | 42.4 | 2.0 | 12.3 | 19.3 |
| CPPF | 82.8 | 44.1 | 0.2 | 0.8 | 1.7 |
| CPPF++ (ours) | 77.6 | 49.4 | 2.0 | 9.1 | 13.1 |
Results on Wild6D. Bold: best, underlined: second best, as marked in the paper.
| Method | 3D25 | 3D50 | 5° 5 cm | 10° 5 cm | 15° 5 cm |
|---|---|---|---|---|---|
| NOCS | 29.2 | 0.9 | 5.3 | 30.5 | 61.4 |
| DualPoseNet | 22.6 | 0.0 | 0.9 | 13.0 | 36.6 |
| SAR-Net | 85.3 | 20.2 | 0.3 | 19.8 | 54.8 |
| RePoNet | 87.4 | 18.5 | 11.0 | 60.6 | 78.0 |
| HS-Pose | 80.7 | 9.6 | 41.1 | 73.9 | 84.6 |
| CPPF | 15.5 | 1.5 | 13.5 | 35.0 | 41.7 |
| CPPF++ (ours) | 53.2 | 8.9 | 64.5 | 96.0 | 96.8 |
| Method | 3D25 | 3D50 | 5° 5 cm | 10° 5 cm | 15° 5 cm |
|---|---|---|---|---|---|
| NOCS | 0.3 | 0.2 | 0.0 | 3.3 | 58.0 |
| DualPoseNet | 18.6 | 4.7 | 2.8 | 13.9 | 26.1 |
| SAR-Net | 39.4 | 0.3 | 0.0 | 0.9 | 19.9 |
| RePoNet | – | – | – | – | – |
| HS-Pose | 100.0 | 17.1 | 6.6 | 41.8 | 67.8 |
| CPPF | 88.7 | 0.3 | 3.3 | 9.4 | 10.9 |
| CPPF++ (ours) | 86.8 | 25.0 | 12.7 | 46.1 | 50.0 |
| Method | 3D25 | 3D50 | 5° 5 cm | 10° 5 cm | 15° 5 cm |
|---|---|---|---|---|---|
| NOCS | 43.4 | 5.7 | 0.0 | 0.1 | 1.0 |
| DualPoseNet | 78.0 | 18.9 | 0.0 | 3.2 | 6.7 |
| SAR-Net | 96.6 | 0.1 | 0.0 | 0.7 | 6.5 |
| RePoNet | 97.4 | 55.2 | 1.0 | 20.3 | 39.9 |
| HS-Pose | 100.0 | 27.2 | 0.6 | 7.7 | 12.2 |
| CPPF | 96.6 | 6.7 | 0.0 | 0.0 | 0.1 |
| CPPF++ (ours) | 100.0 | 93.2 | 7.9 | 47.1 | 65.6 |
Results on PhoCAL. RePoNet does not report the can category. Bold: best, underlined: second best, as marked in the paper.
| Method | 3D25 | 3D50 | 20° 5 cm | 40° 5 cm | 60° 5 cm |
|---|---|---|---|---|---|
| NOCS | 3.3 | 0.0 | 2.3 | 2.3 | 2.3 |
| DualPoseNet | 1.4 | 0.0 | 4.3 | 9.3 | 15.8 |
| SAR-Net | 2.5 | 0.0 | 0.1 | 6.3 | 14.2 |
| RePoNet | 1.9 | 0.1 | 9.6 | 20.2 | 20.2 |
| HS-Pose | 0.2 | 0.0 | 0.5 | 10.5 | 15.1 |
| CPPF | 0.0 | 0.0 | 13.3 | 15.5 | 15.5 |
| CPPF++ (ours) | 6.9 | 0.5 | 11.1 | 13.7 | 22.9 |
| Method | 3D25 | 3D50 | 20° 5 cm | 40° 5 cm | 60° 5 cm |
|---|---|---|---|---|---|
| NOCS | 1.7 | 0.3 | 0.5 | 0.5 | 0.5 |
| DualPoseNet | 61.3 | 2.3 | 1.4 | 16.1 | 33.3 |
| SAR-Net | 4.8 | 0.1 | 1.2 | 28.8 | 55.6 |
| RePoNet | 40.3 | 2.4 | 11.5 | 37.9 | 66.2 |
| HS-Pose | 11.2 | 0.0 | 1.4 | 10.5 | 17.3 |
| CPPF | 32.7 | 3.4 | 14.5 | 37.6 | 42.1 |
| CPPF++ (ours) | 38.5 | 15.6 | 79.5 | 92.2 | 92.2 |
| Method | 3D25 | 3D50 | 20° 5 cm | 40° 5 cm | 60° 5 cm |
|---|---|---|---|---|---|
| NOCS | 4.9 | 2.4 | 0.0 | 1.7 | 1.9 |
| DualPoseNet | 60.4 | 28.3 | 0.2 | 0.8 | 2.1 |
| SAR-Net | 49.5 | 0.4 | 0.0 | 0.4 | 0.9 |
| RePoNet | 21.1 | 1.4 | 0.5 | 1.5 | 2.3 |
| HS-Pose | 8.3 | 0.1 | 0.0 | 0.6 | 0.8 |
| CPPF | 35.8 | 15.2 | 0.7 | 1.0 | 2.3 |
| CPPF++ (ours) | 54.2 | 21.2 | 22.0 | 38.9 | 47.2 |
Results on DiversePose 300, our new benchmark with diverse, non-upright poses. Note the looser rotation thresholds. Bold: best, underlined: second best, as marked in the paper.
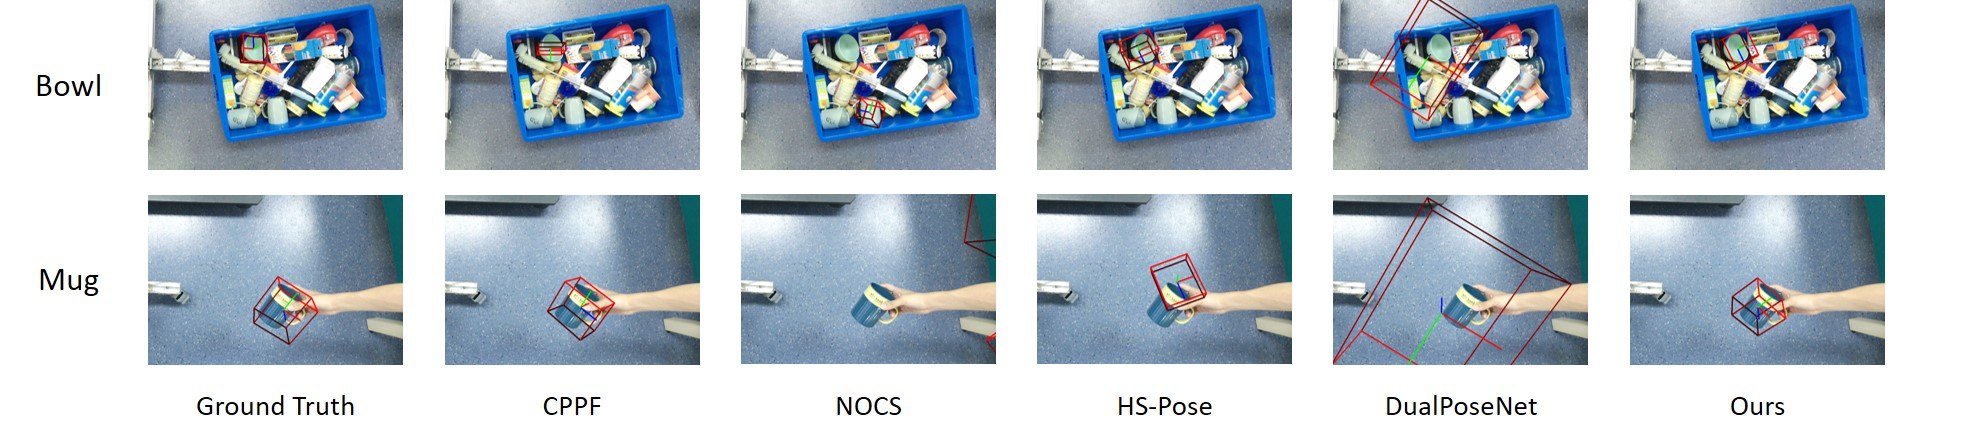
DiversePose 300
Existing benchmarks such as NOCS REAL275, Wild6D and PhoCAL are biased toward upright poses. DiversePose 300 contains 305 annotated real RGB-D frames of bottles, bowls and mugs in diverse, non-upright poses, captured in a crowded box, on a desk, and held in a hand.
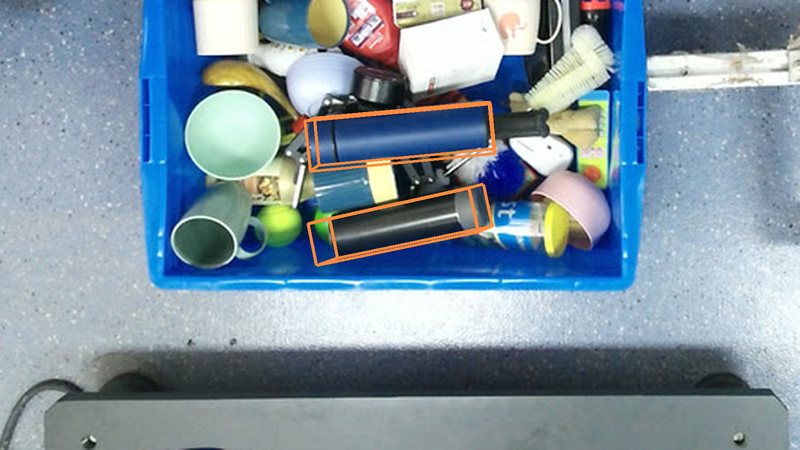
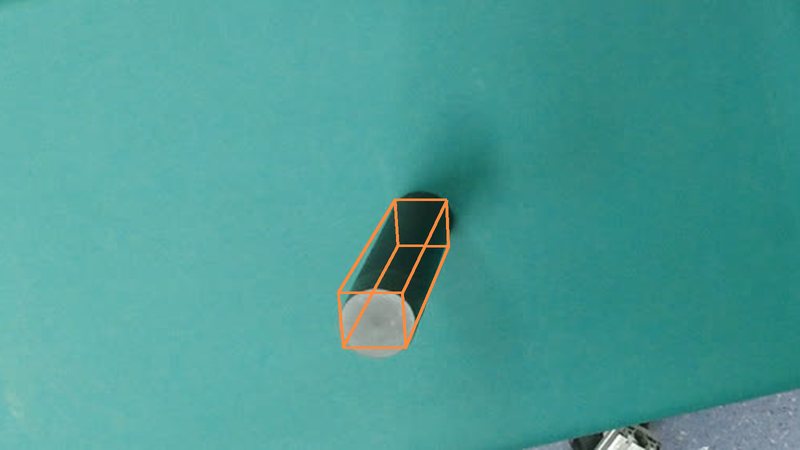
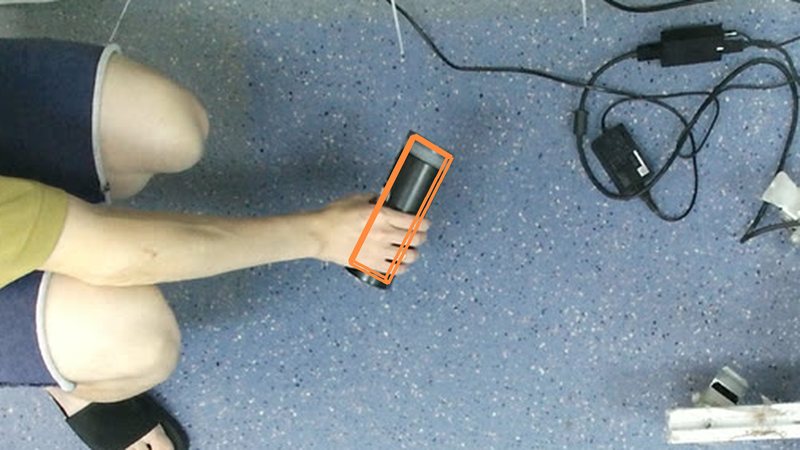
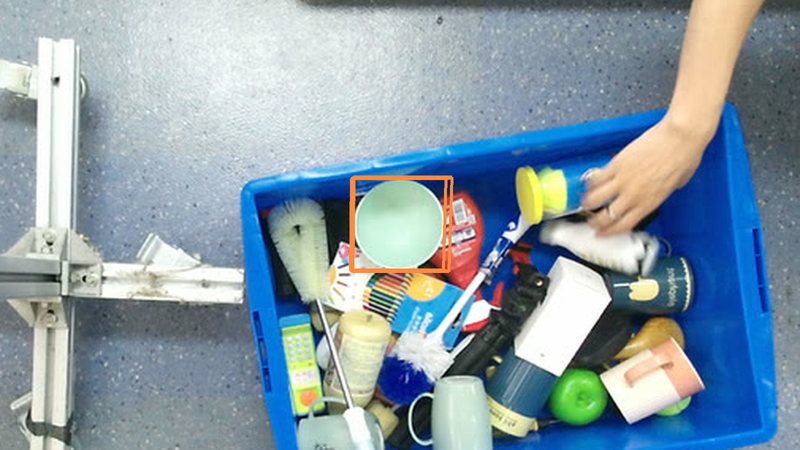
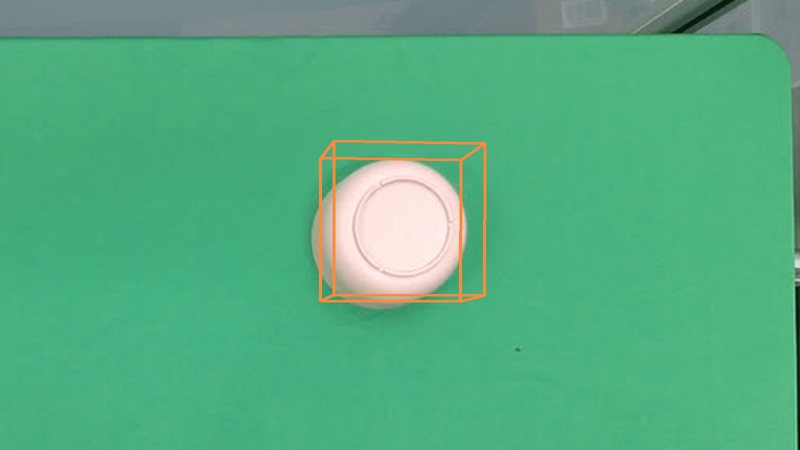
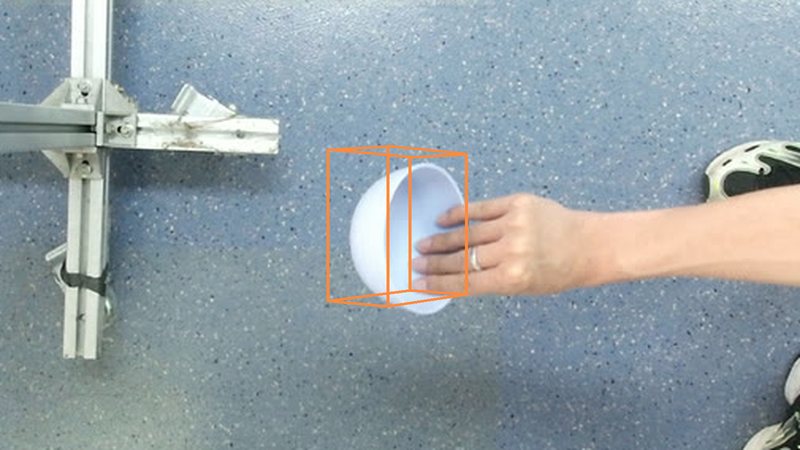
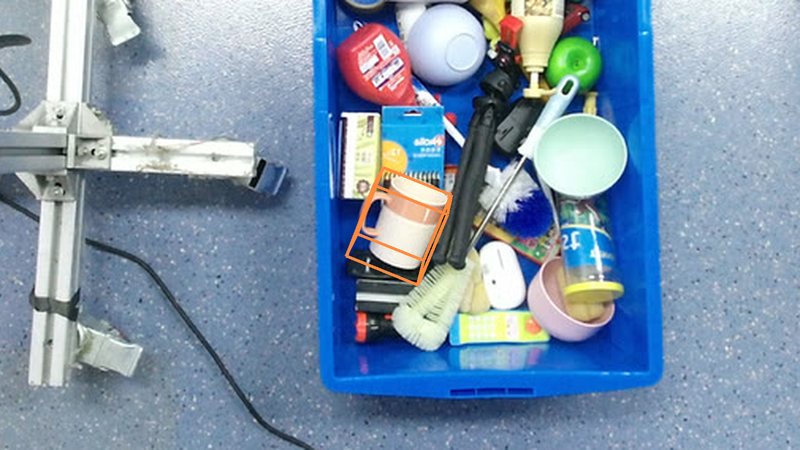
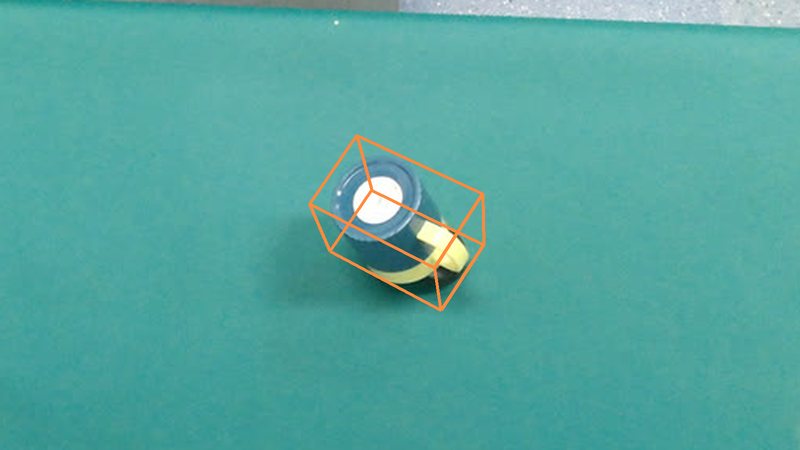
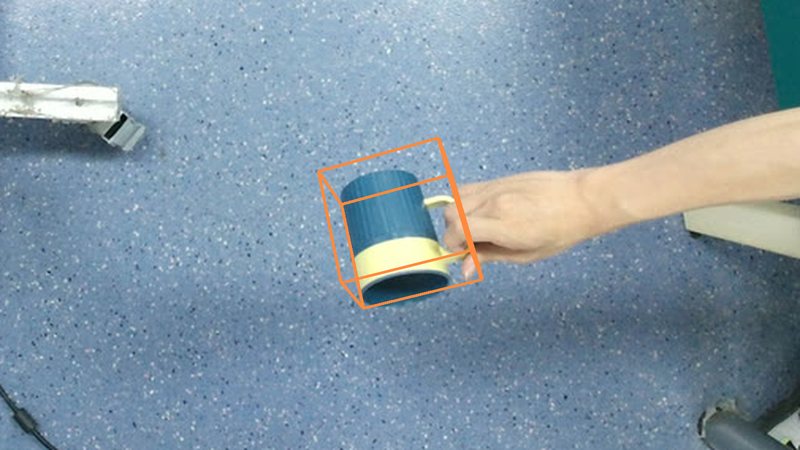
Orange boxes: ground-truth 3D annotations. The release provides RGB images, colored point clouds, 3D box labels and camera intrinsics.
Read the full abstract
Object pose estimation constitutes a critical area within the domain of 3D vision. While contemporary state-of-the-art methods that leverage real-world pose annotations have demonstrated commendable performance, the procurement of such real training data incurs substantial costs. This paper focuses on a specific setting wherein only 3D CAD models are utilized as a priori knowledge, devoid of any background or clutter information. We introduce a novel method, CPPF++, designed for sim-to-real category-level pose estimation. This method builds upon the foundational point-pair voting scheme of CPPF, reformulating it through a probabilistic view. To address the challenge posed by vote collision, we propose a novel approach that involves modeling the voting uncertainty by estimating the probabilistic distribution of each point pair within the canonical space. Furthermore, we augment the contextual information provided by each voting unit through the introduction of N-point tuples. To enhance the robustness and accuracy of the model, we incorporate several innovative modules, including noisy pair filtering, online alignment optimization, and a tuple feature ensemble. Alongside these methodological advancements, we introduce a new category-level pose estimation dataset, named DiversePose 300. Empirical evidence demonstrates that our method significantly surpasses previous sim-to-real approaches and achieves comparable or superior performance on novel datasets.
BibTeX
@article{You_2024,
  title={CPPF++: Uncertainty-Aware Sim2Real Object Pose Estimation by Vote Aggregation},
  ISSN={1939-3539},
  url={http://dx.doi.org/10.1109/TPAMI.2024.3419038},
  DOI={10.1109/tpami.2024.3419038},
  journal={IEEE Transactions on Pattern Analysis and Machine Intelligence},
  publisher={Institute of Electrical and Electronics Engineers (IEEE)},
  author={You, Yang and He, Wenhao and Liu, Jin and Xiong, Hongkai and Wang, Weiming and Lu, Cewu},
  year={2024},
  pages={1–16}
}