Shape dough with tools, without demonstrations
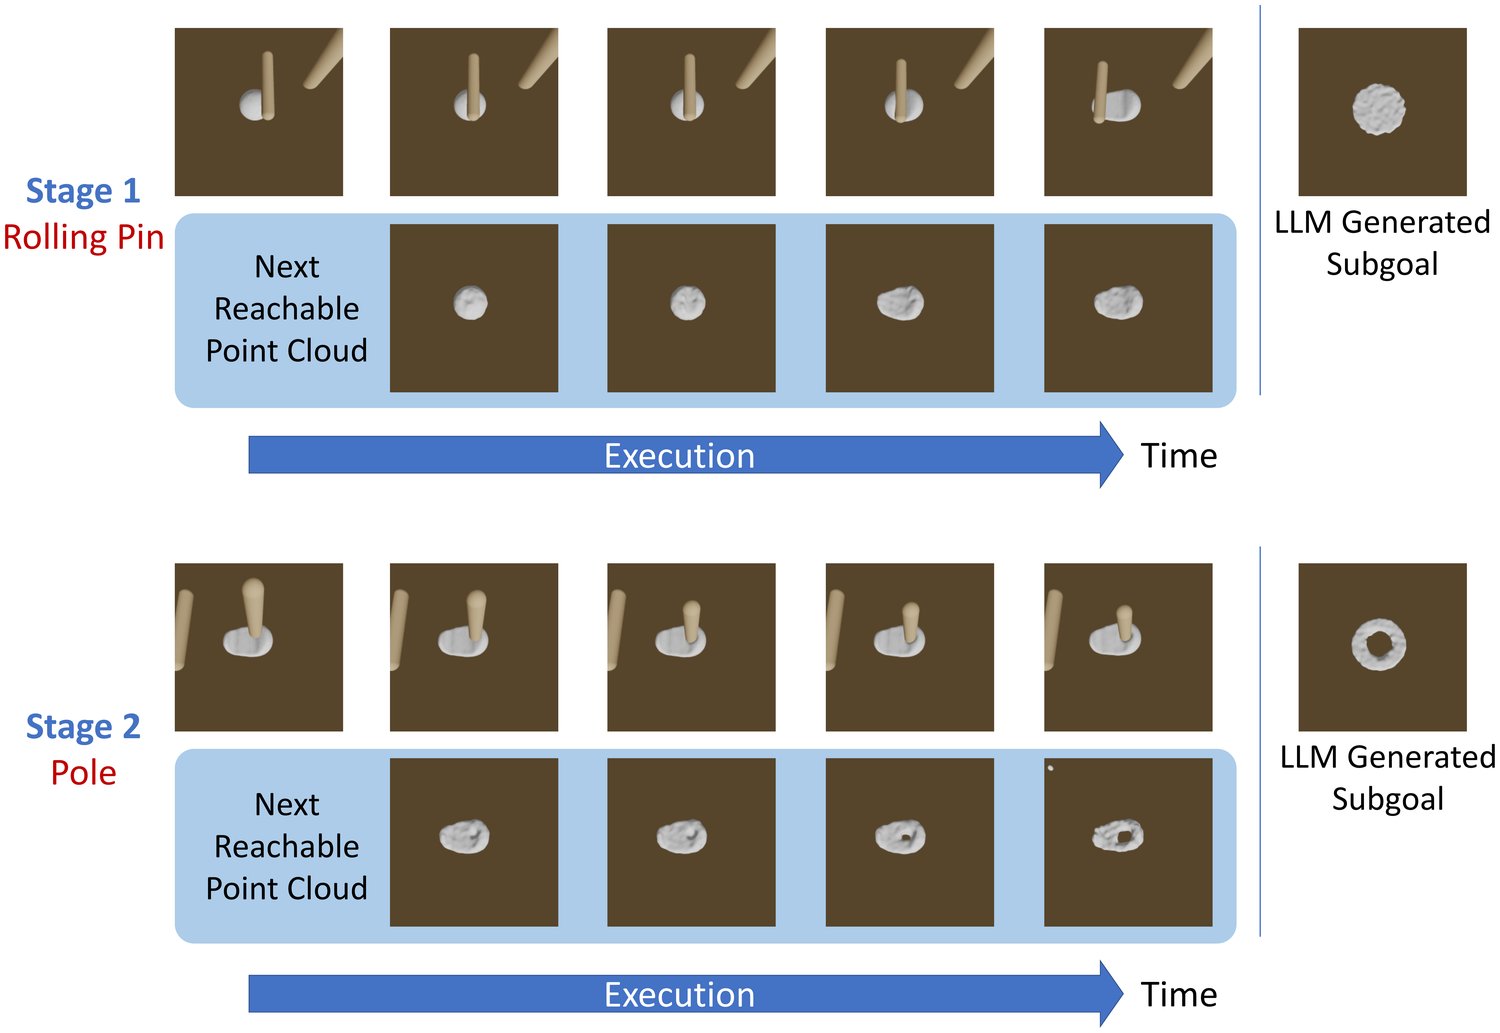
Dough changes shape with every touch, and making a donut takes several tools in the right order. Learned methods need demonstrations, which are hard to collect for long tasks and do not carry over to new shapes. Make a Donut plans in two levels instead: GPT-4 splits the task into stages, picking one tool per stage and writing Python code for the stage's goal shape; a closed-loop planner then reaches each goal by stepping through the space of Earth Mover's Distance (EMD) and finding tool motions with differentiable physics. Nothing is trained for the task.
no demonstrations and no task-specific training: a new task is one line added to the prompt
success on Donut, Baguette and Two pancakes; no baseline gets above 20% on any of them
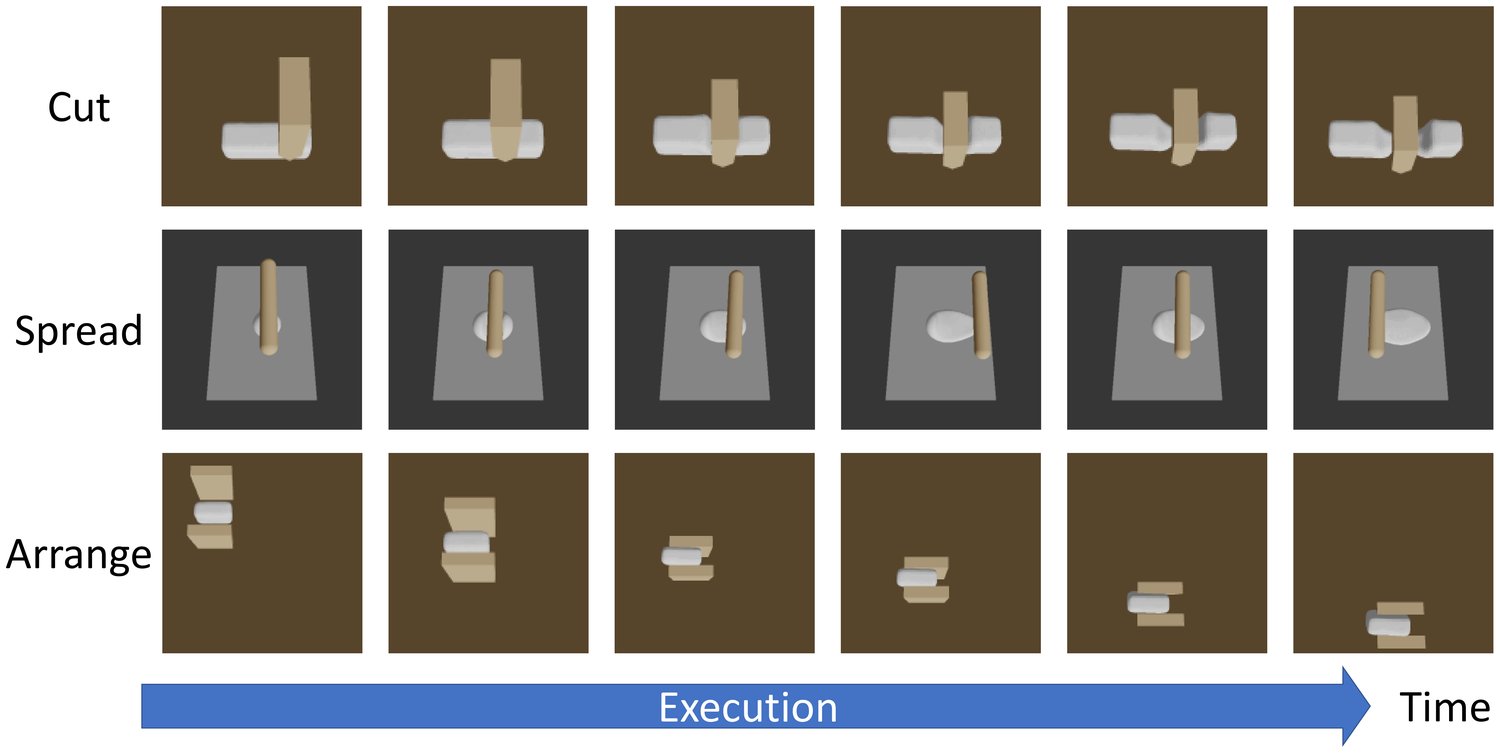
success on the single-tool tasks Spread, Cut and Arrange
planning rate: 0.34 s per action on a GPU, with 54 ms to find the next reachable point cloud
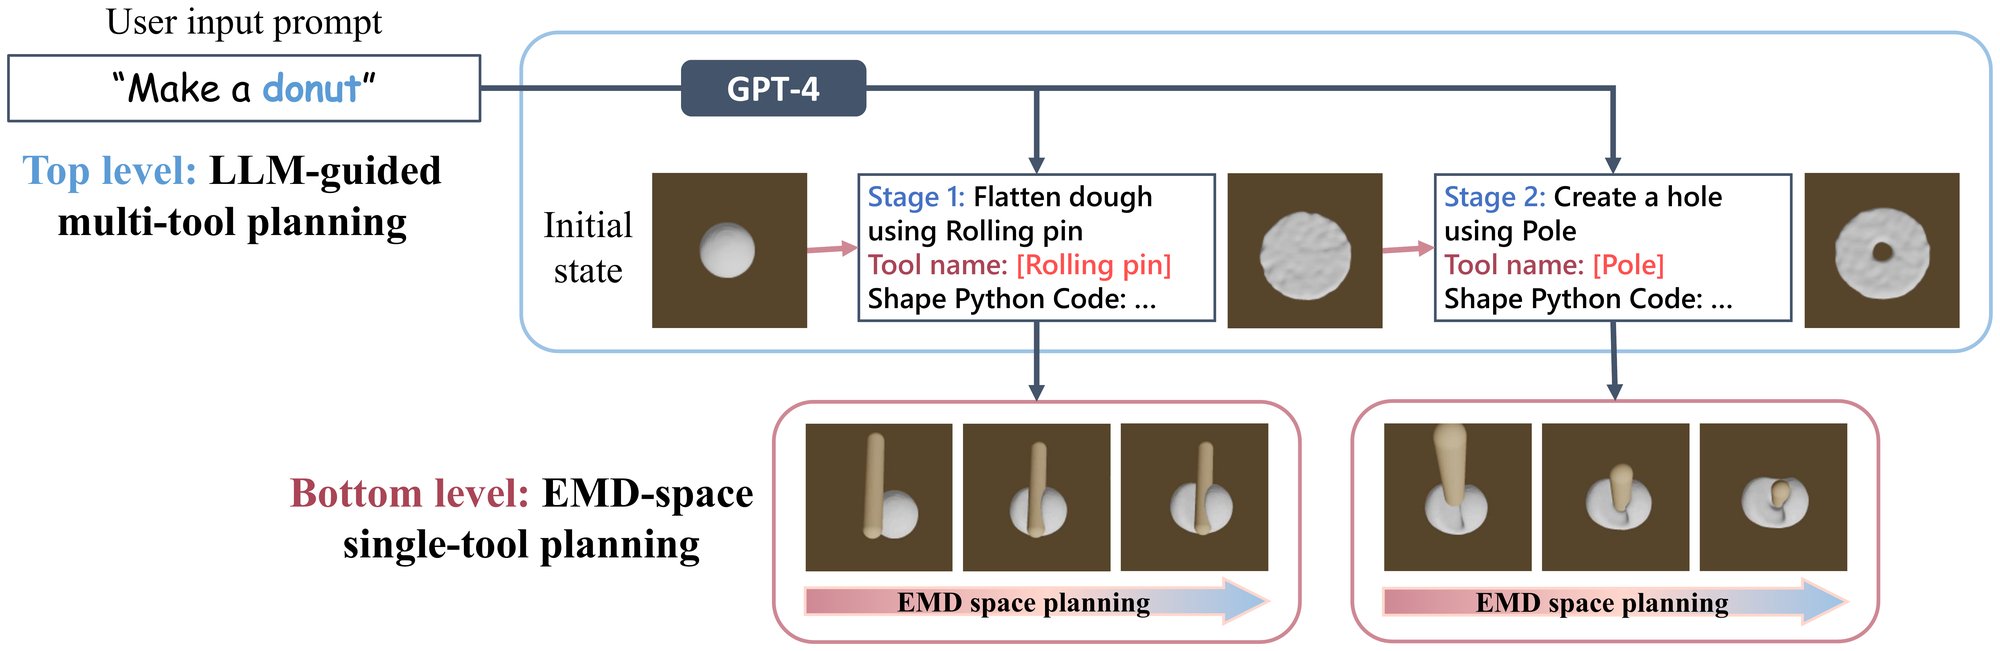
GPT-4 writes the plan, one tool per stage
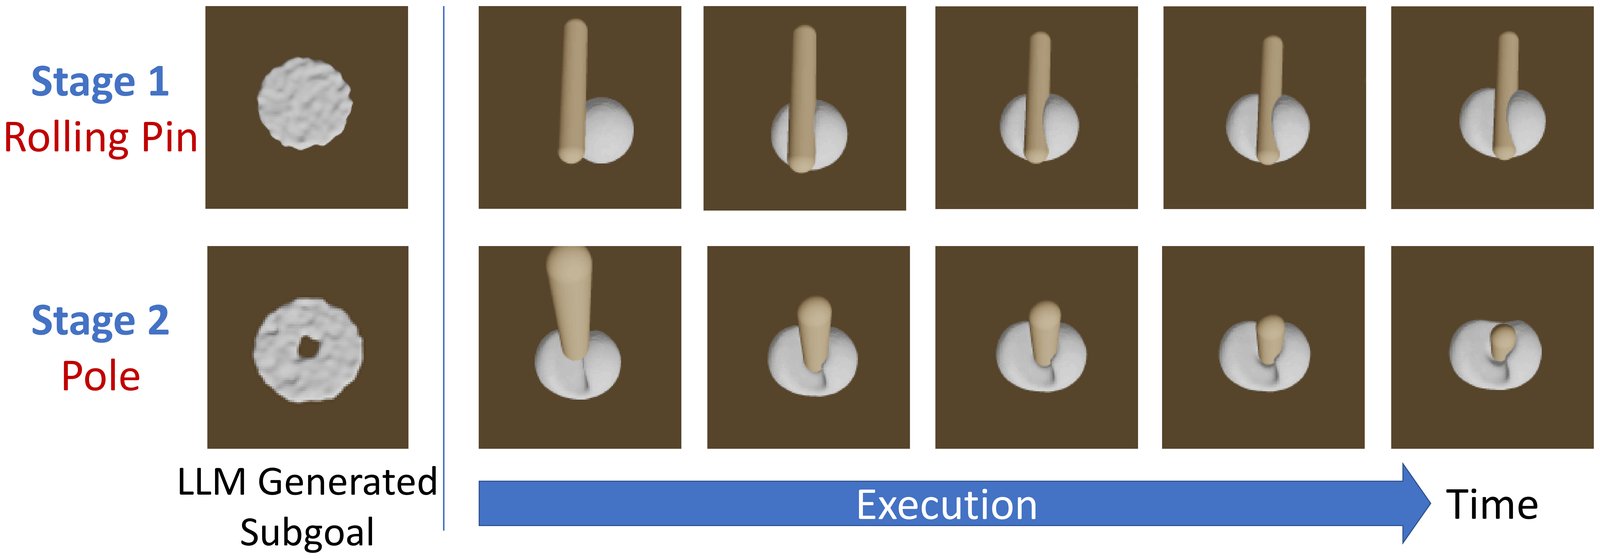
One prompt, shared by all tasks, describes four tools: a rolling pin, a gripper, a knife and a pole. A task is a single extra line, such as “The dough is initially a round ball at (0, 0, 0) with radius 1. Make a simple donut.” For every stage, GPT-4 answers with a one-line explanation, the tool, numpy code that builds the stage's goal point cloud, and the location and volume of each piece. Only the code is run; the rest is there to make GPT-4 reason before it writes the shape. Each stage uses one tool on one piece of dough.
Two guidelines keep the shapes realistic
Volume preserving: the dough cannot grow or shrink, so GPT-4 must derive each new shape's dimensions from the old volume. Chain of reasoning: it writes the formulas out step by step before the code. Without them, the planned shapes drift far from the dough's volume:
| Prompt | Donut | Baguette | Two pancakes |
|---|---|---|---|
| Without volume preserving and chain reasoning | 73.9% | 42.5% | 65.0% |
| With both (ours) | 9.8% | 38.9% | 0.0% |
Planning in EMD space
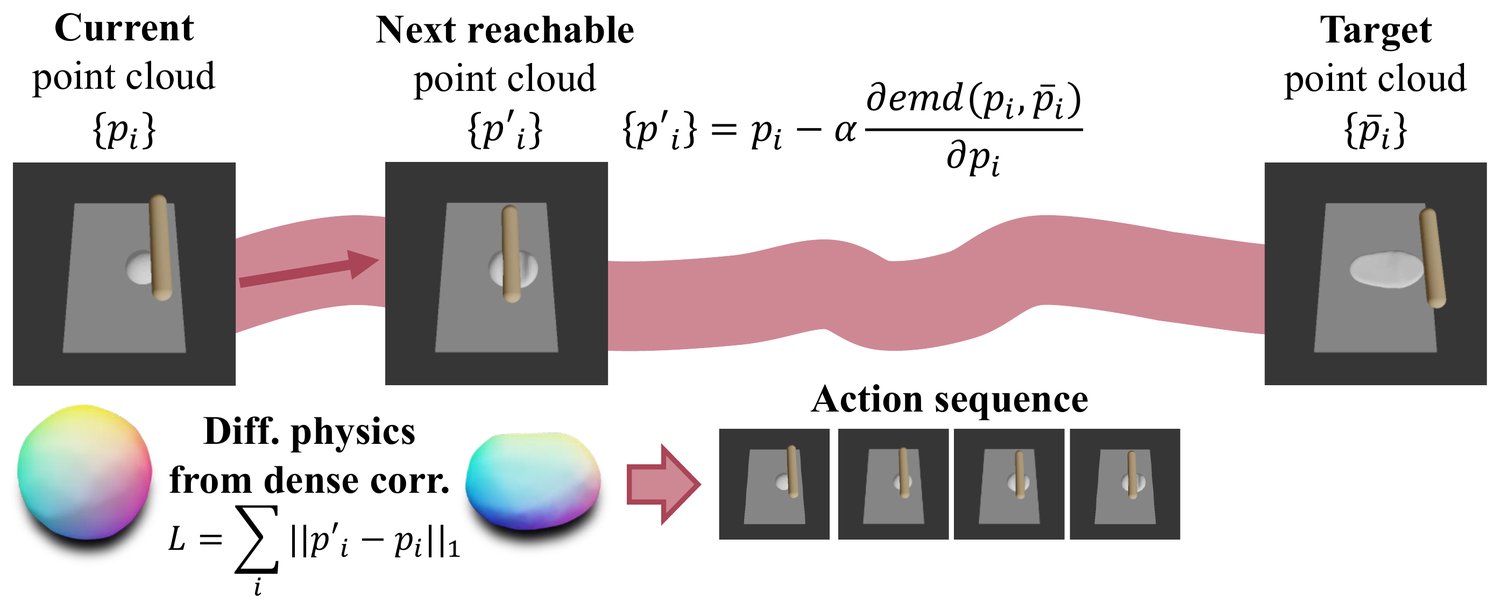
Within a stage, the planner does not jump to the goal. It moves the current point cloud a few small steps toward the goal along the gradient of the Earth Mover's Distance, which gives the next reachable point cloud. Because EMD matches points one to one, every particle gets its own target:
Try it below: pick a task and watch the particles step from one GPT-4 subgoal to the next. Colours follow each particle, so you can see the one-to-one matching.
lines: next reachable point cloud, 20 steps ahead
Task
GPT-4's stages
A top-view illustration in your browser: simple shapes for each stage, exact EMD matching between consecutive goals, and the constant-size steps of the equation above. In the real method, tools and differentiable physics decide how the dough actually moves.
- Next reachable target20 EMD steps from the current dough give a nearby, reachable target with a per-particle correspondence.
- Point-to-point lossThe tool's actions are optimized so each particle moves to its own target, which gives better gradients than a plain EMD loss.
- Where to put the toolAt the start of a stage the tool goes where the biggest deformation is about to happen.
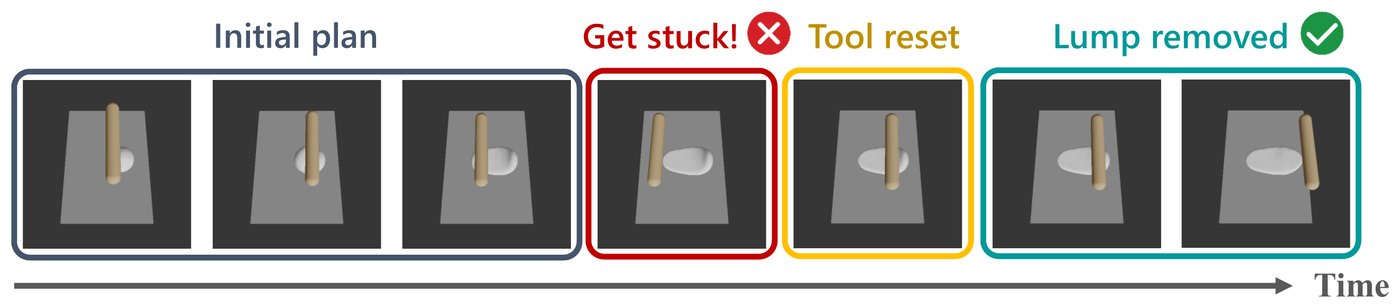
- Reset when stuckIf the EMD to the goal stops dropping, the tool is placed again, which escapes local minima.
Long tasks that baselines cannot do
Compared with gradient-based optimization through differentiable physics alone, the planner PASTA, behaviour cloning and the offline RL method SAC-N. Demonstrations are hard to get for long tasks, so BC and SAC-N get one hand-made demonstration per task and PASTA uses its model trained on single-tool demonstrations. The score is the normalized decrease in EMD to the target (1 means reached); success uses a per-task threshold.
All numbers
| Method | Multiple-tool tasks | Single-tool tasks | ||||
|---|---|---|---|---|---|---|
| Donut | Baguette | Two pancakes | Spread | Cut | Arrange | |
| Diff. Physics | 0.141 / 0% | 0.175 / 20% | 0.583 / 0% | 0.184 / 20% | 0.401 / 60% | 0.296 / 20% |
| PASTA | 0.020 / 0% | -0.116 / 0% | -0.856 / 0% | 0.155 / 20% | 0.060 / 40% | 0.052 / 0% |
| BC | 0.001 / 0% | -0.606 / 0% | 0.220 / 0% | 0.441 / 60% | -0.488 / 20% | -0.512 / 0% |
| SAC-N | 0.003 / 0% | -0.306 / 0% | 0.127 / 0% | 0.000 / 0% | -2.827 / 0% | 0.267 / 0% |
| Ours | 0.346 / 75% | 0.501 / 75% | 0.858 / 65% | 0.680 / 100% | 0.685 / 100% | 0.981 / 100% |
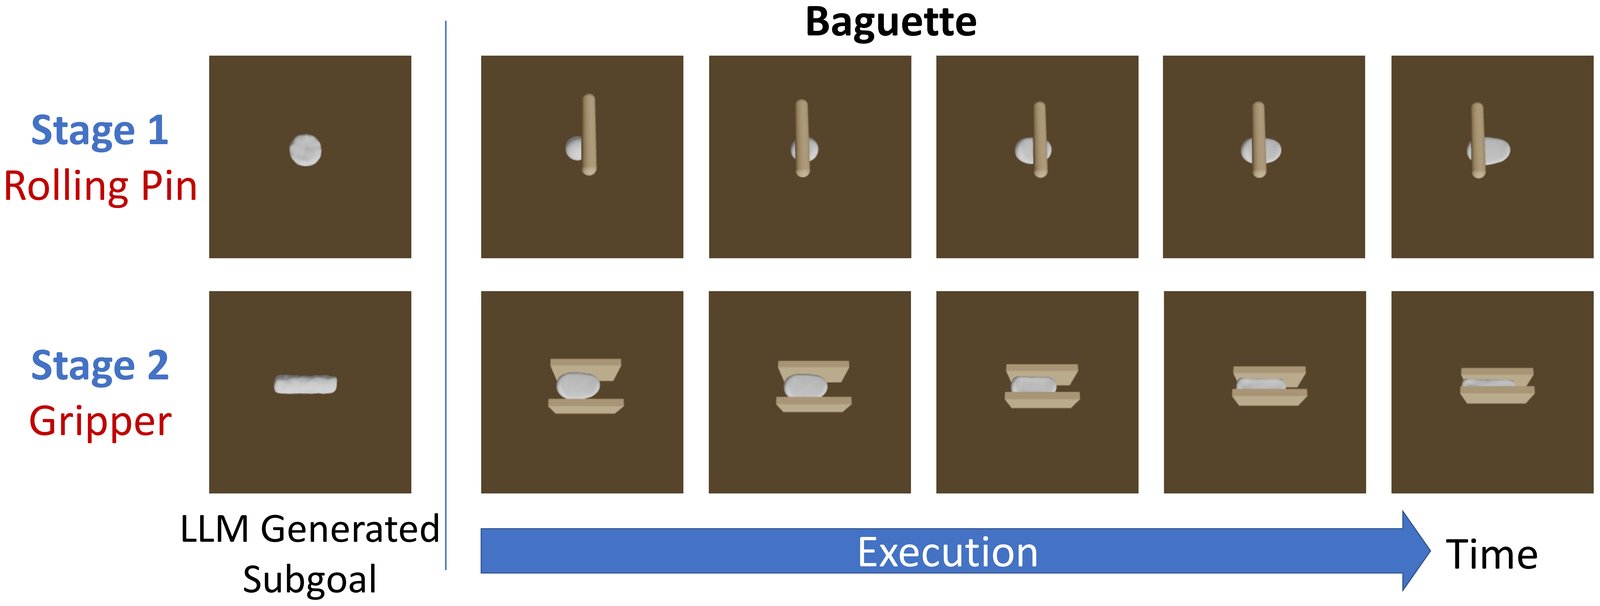
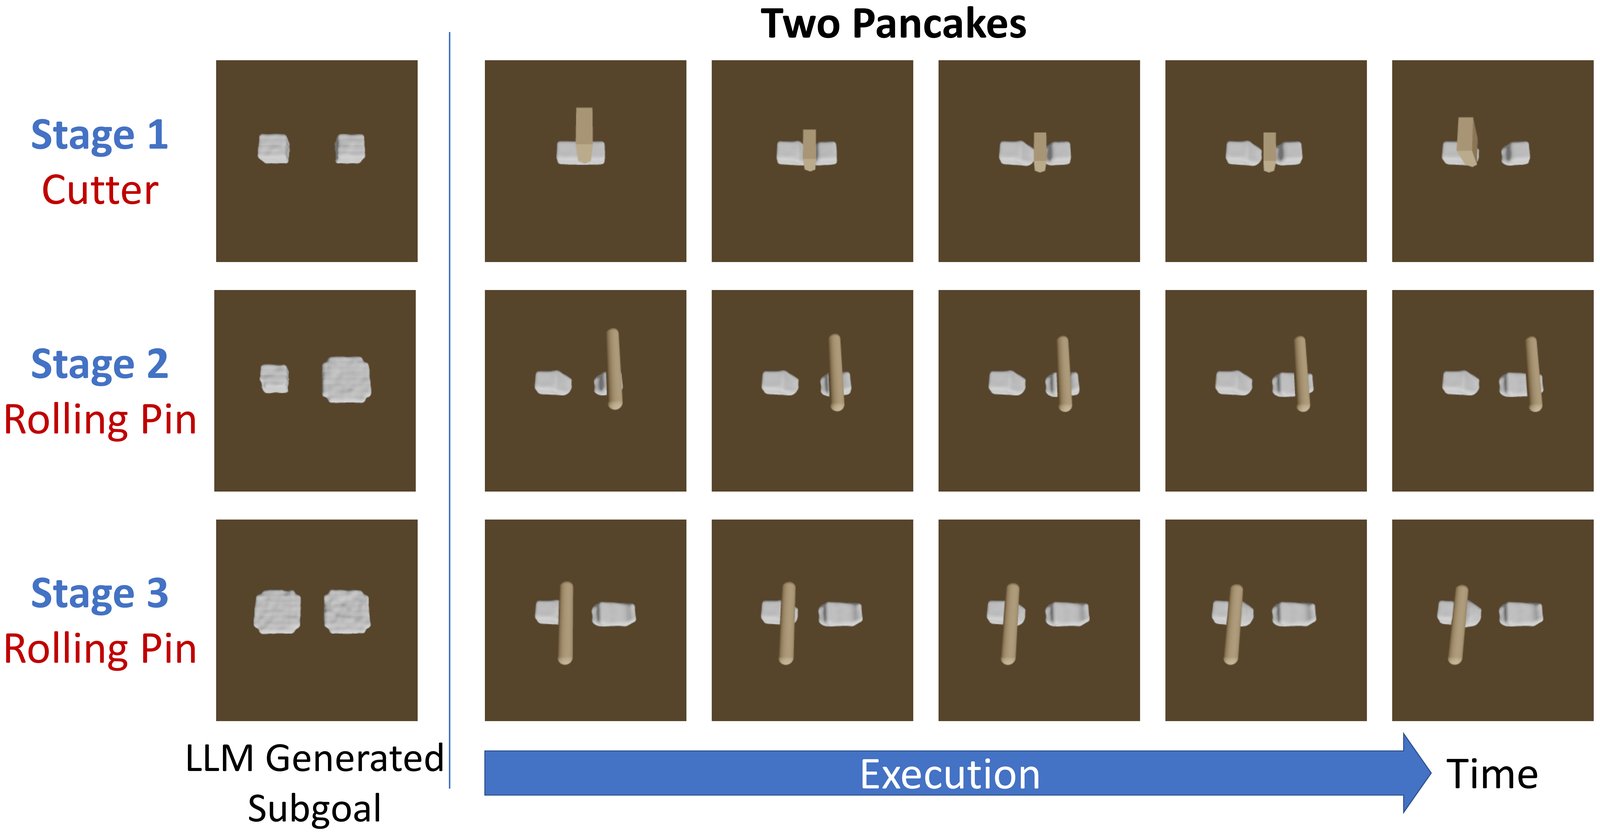
Four GPT-4 plans per task, all executed
For each long task we ask GPT-4 four times and run every plan. The clips show one run per plan, one clip per stage. The plans differ in their details, yet the same planner carries all of them out.
Every piece is needed
Without GPT-4's plan, the EMD planner has no reachable intermediate goals and fails every long task. Without the volume-preserving and chain-of-reasoning guidelines, the plans' shapes are off and success drops to at most 25%. For single tools, removing the point-to-point loss hurts the most; initial tool placement and tool resetting matter less but still help.
Values as printed on the paper's ablation charts.
From simulation to real dough
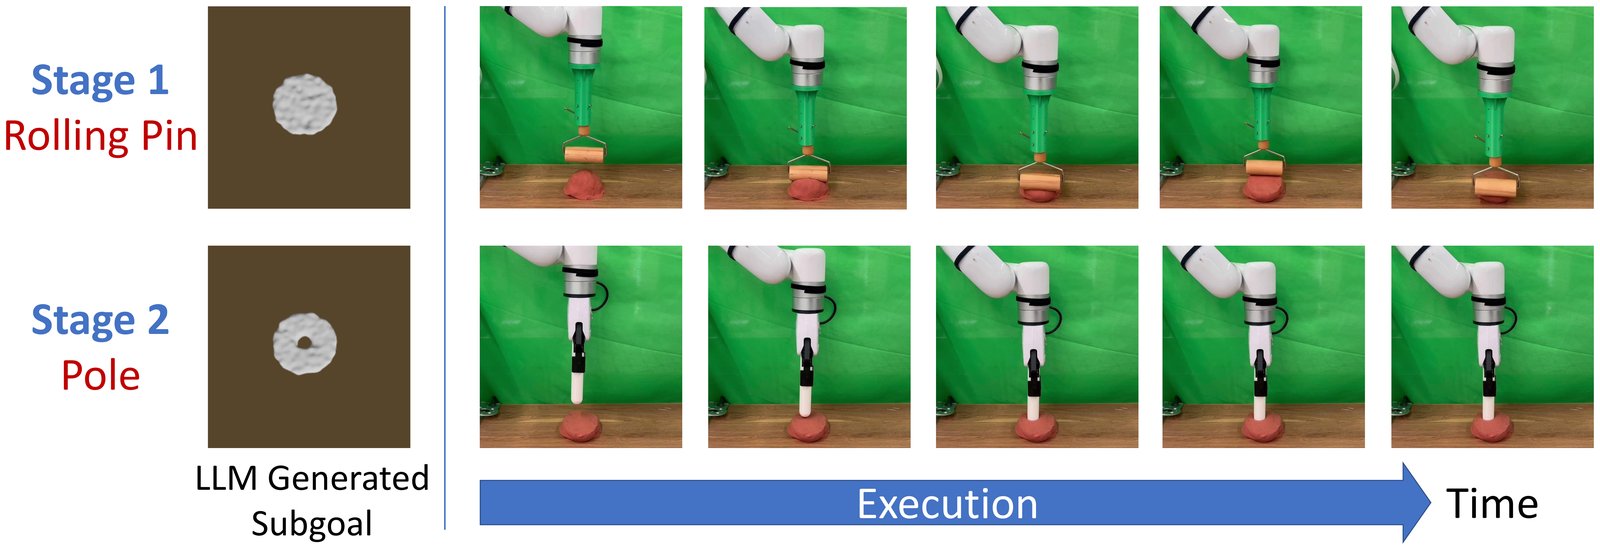
On a UFACTORY xArm 6, four depth cameras around the dough are fused with TSDF fusion into particles, so each stage starts from the real dough's state. The planner moves from there to GPT-4's goal in simulation, and the actions are replayed on the robot.
When a shape is hard to write as code
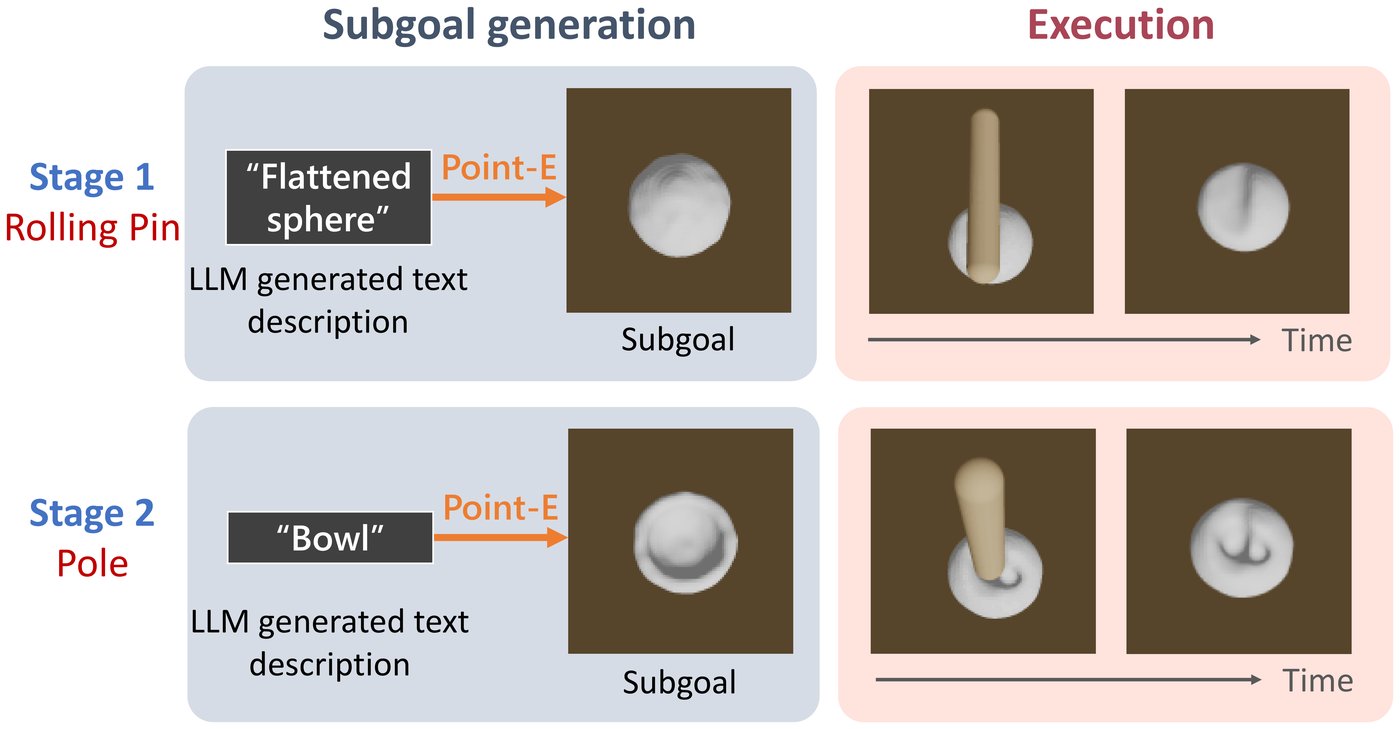
GPT-4 can only plan shapes it can describe with simple numpy code. For harder ones, it can describe each stage's shape in words instead, and a text-to-3D model turns the words into point clouds. To make a bowl, GPT-4 asks for a “flattened sphere” and then a “bowl”; Point-E generates both, and the same EMD-space planner executes them.
- Imperfect subgoals are fine: GPT-4's shapes are not always exactly reachable; the closed loop still gets close.
- Speed: about 3 actions per second on a GPU.
Try the prompts yourself
Paste the shared template into GPT-4 and end it with one line describing the dough and the goal. These are the exact prompts from the paper.
The task lines are also available as exp_donut.txt, exp_baguette.txt and exp_pancakes.txt.
Read the full abstract
Deformable object manipulation stands as one of the most captivating yet formidable challenges in robotics. While previous techniques have predominantly relied on learning latent dynamics through demonstrations, typically represented as either particles or images, there exists a pertinent limitation: acquiring suitable demonstrations, especially for long-horizon tasks, can be elusive. Moreover, basing learning entirely on demonstrations can hamper the model's ability to generalize beyond the demonstrated tasks. In this work, we introduce a demonstration-free hierarchical planning approach capable of tackling intricate long-horizon deformable manipulation tasks without necessitating any training. We employ large language models (LLMs) to articulate a high-level, stage-by-stage plan corresponding to a specified task. For every individual stage, the LLM provides both the tool's name and the Python code to craft intermediate subgoal point clouds. With the tool and subgoal for a particular stage at our disposal, we present a granular closed-loop model predictive control strategy. This leverages Differentiable Physics with Point-to-Point correspondence (DiffPhysics-P2P) loss in the Earth Mover Distance (EMD) space, applied iteratively. Experimental findings affirm that our technique surpasses multiple benchmarks in dough manipulation, spanning both short and long horizons. Remarkably, our model demonstrates robust generalization capabilities to novel and previously unencountered complex tasks without any preliminary demonstrations. We further substantiate our approach with experimental trials on real-world robotic platforms.
BibTeX
@article{you2025make,
  title={Make a Donut: Hierarchical EMD-Space Planning for Zero-Shot Deformable Manipulation With Tools},
  author={You, Yang and Shen, Bokui and Deng, Congyue and Geng, Haoran and Wei, Songlin and Wang, He and Guibas, Leonidas},
  journal={IEEE Robotics and Automation Letters},
  volume={10},
  number={4},
  pages={3270--3277},
  year={2025},
  doi={10.1109/LRA.2025.3537899}
}