From a single image to an editable CAD program
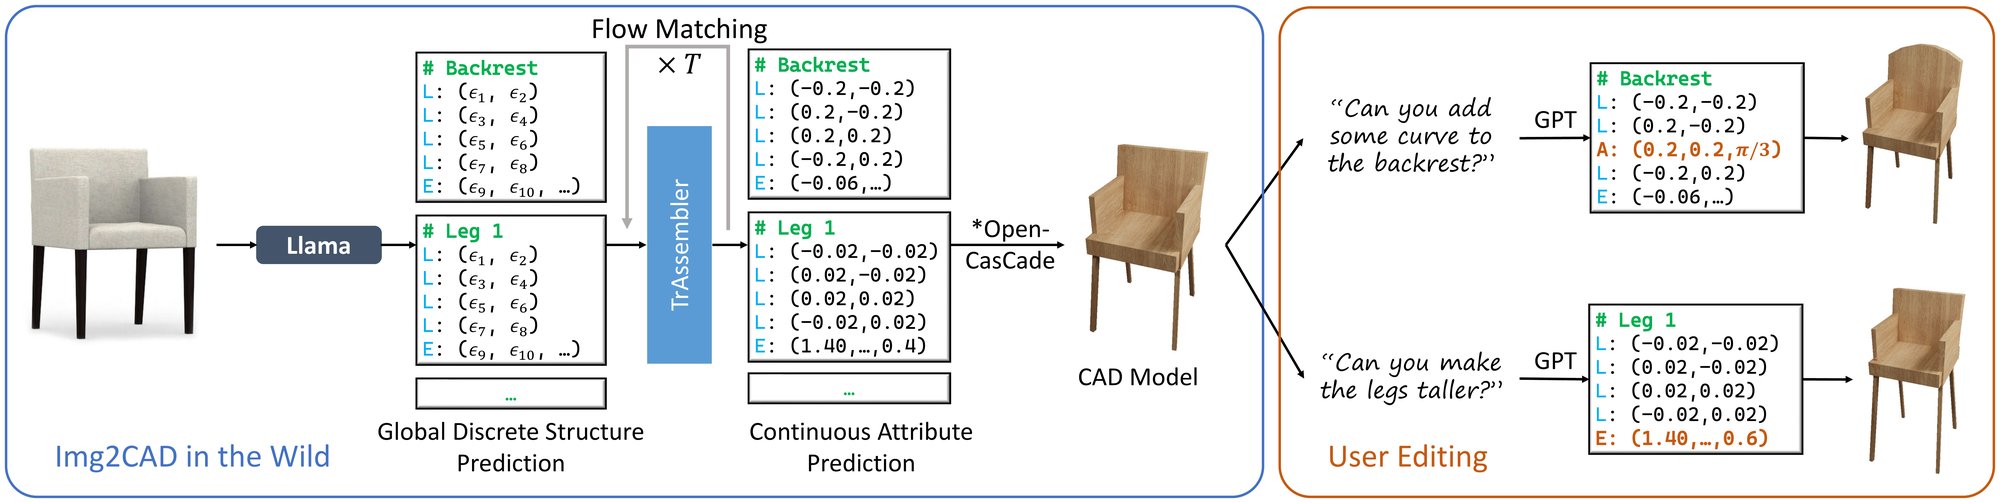
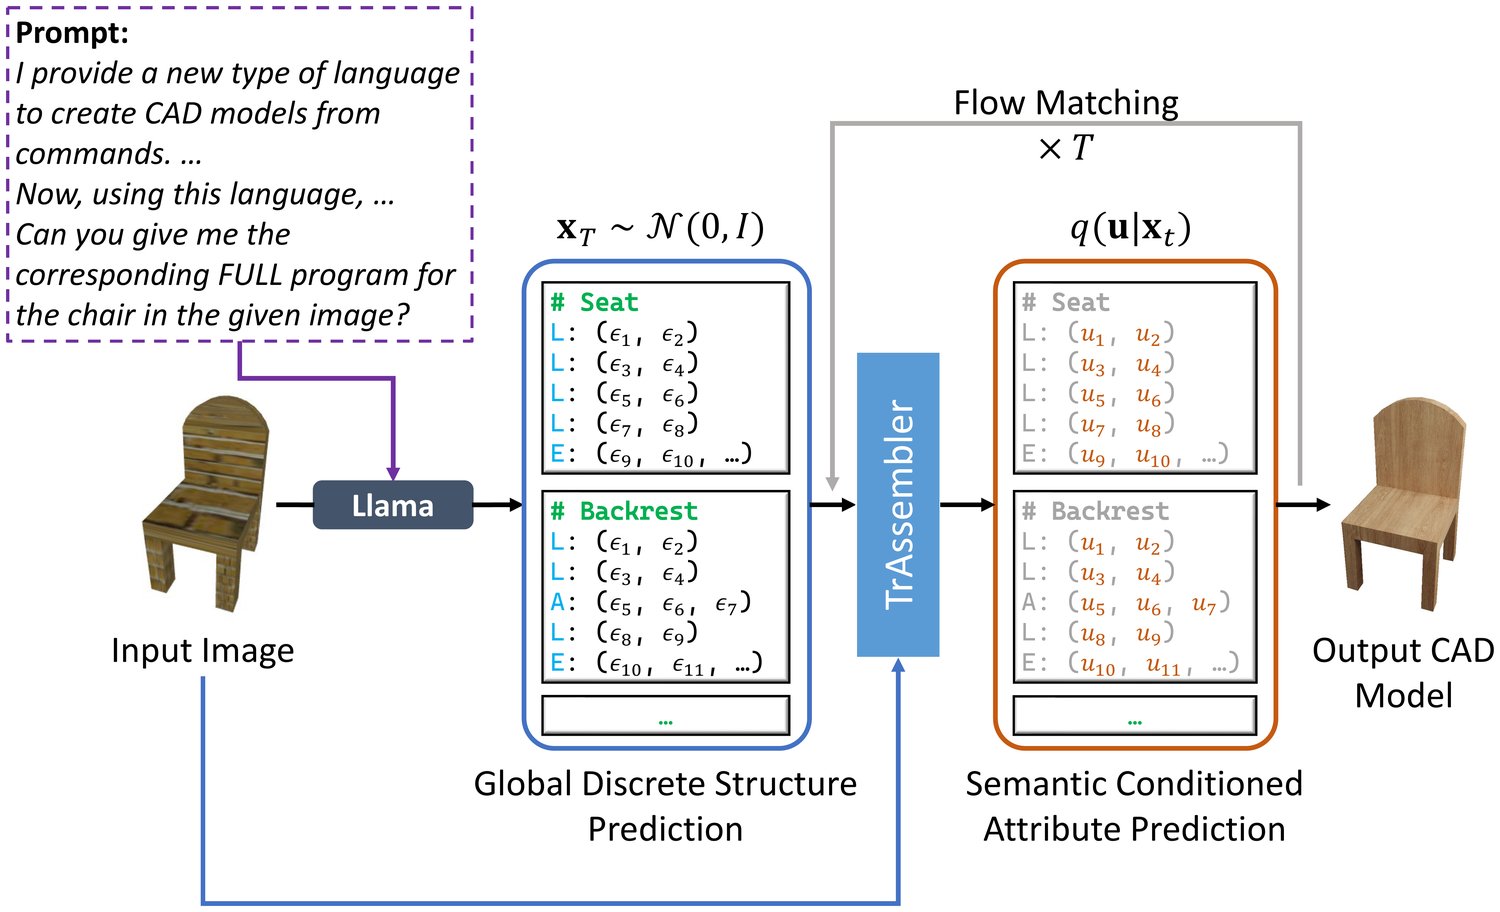
A CAD model is a program: a sequence of discrete commands (lines, arcs, circles, extrusions), each with continuous numbers (coordinates, angles, distances). Predicting both from pixels at once is hard. Img2CAD splits the job: a finetuned Llama 3.2 vision-language model writes the program's structure, naming each part, and TrAssembler, a transformer flow-matching model, fills in the numbers.
average Chamfer distance over chairs, tables and cabinets, 2.6× lower than the best baseline (0.311)
part-segmentation accuracy of the output over the best baseline, DeepCAD trained end to end
part-segmentation mIoU over the same baseline: the parts land where they should
ShapeNet chairs, tables and cabinets turned into CAD programs, released as a dataset
A CAD model is a short program
Img2CAD uses the sketch-and-extrude language of tools such as Fusion 360 and OpenCascade. A sketch is a closed loop of lines L: (x, y), arcs A: (x, y, α) and circles R: (x, y, r). An extrusion E turns it into a solid: three angles and an origin place the sketch, the last number is the distance, and the extrusion either joins the model or cuts it. Try it on a chair: the buttons change the program's structure, the sliders only change numbers.
Structure which commands
Attributes the numbers ·
A hand-written program in the paper's CAD language, built into a mesh in your browser (simple extrusion code, not OpenCascade). As in Img2CAD's programs, a comment names each part; changed numbers light up in orange.
Structure from a VLM, numbers from a flow model
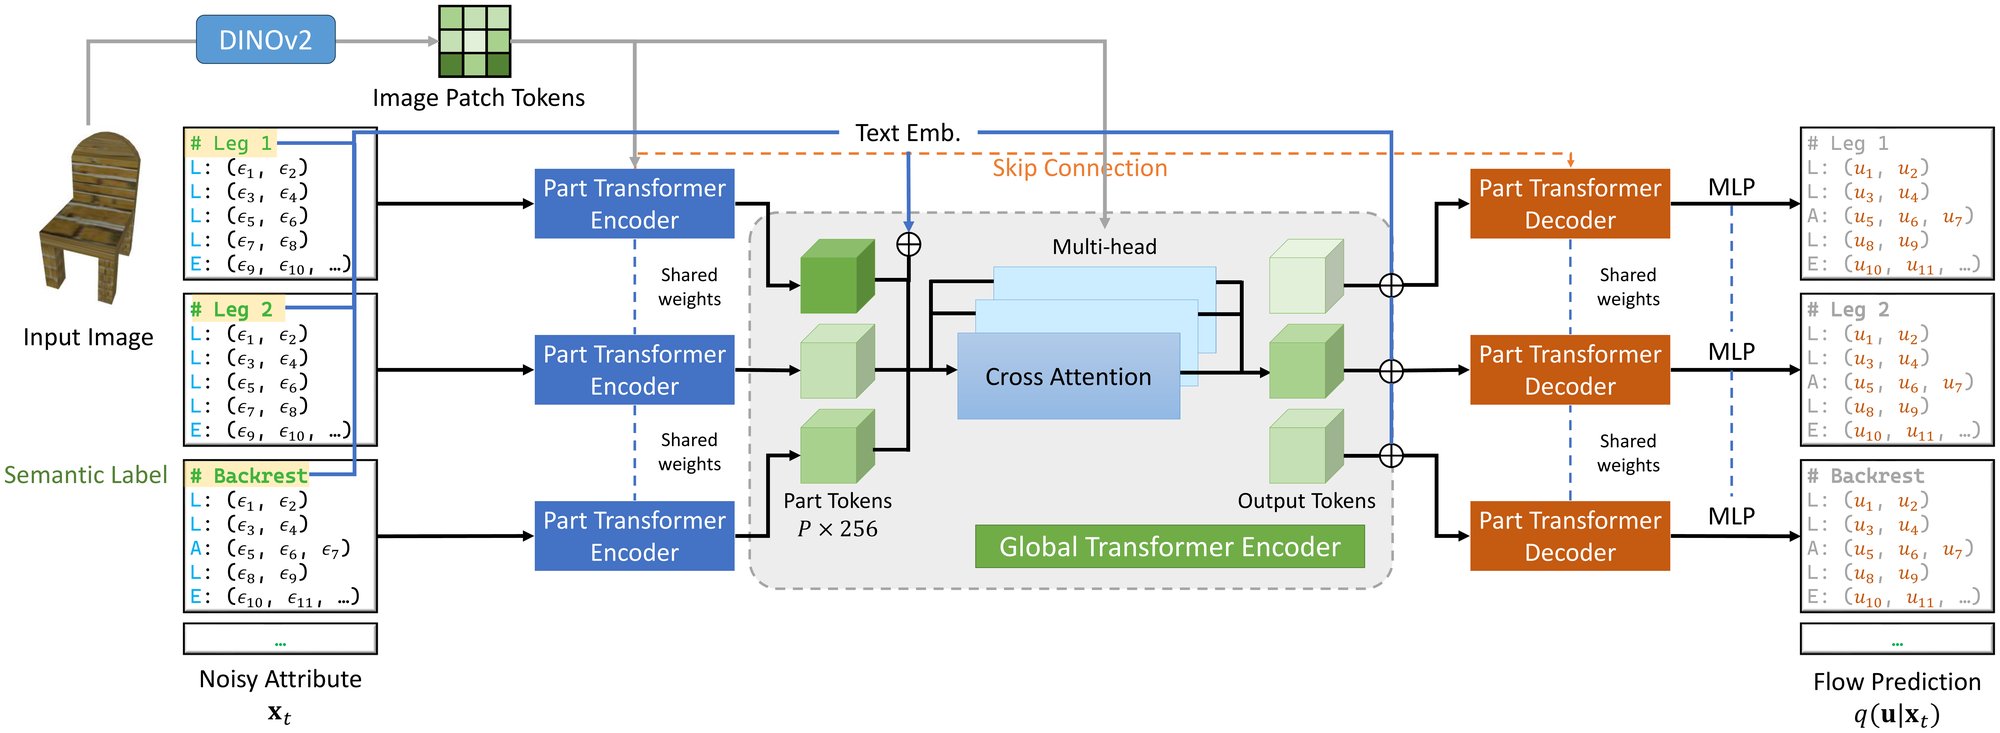
One model predicting a whole program mixes a combinatorial problem (which parts, which commands) with a continuous one (where, how big). Img2CAD conditionally factorizes it: the structure comes first, and the numbers are predicted given the structure.
- StructureA finetuned Llama 3.2 reads the image and writes each part's name and command types, with placeholders instead of numbers.
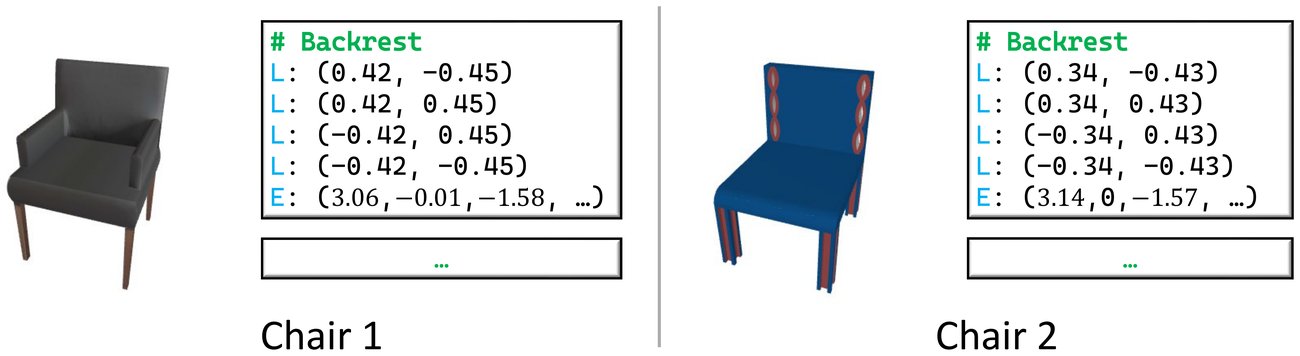
- Shared part namesNames such as backrest or leg stay consistent across shapes, so numbers can be learned across chairs whose structures differ.
- TrAssemblerPart transformers read DINOv2 image features; a global transformer relates the parts, with CLIP embeddings of their names; decoders output every number.
- Flow matching + symmetryNumbers are sampled from noise with GMFlow. At test time each step is nudged toward the mirror or rotational symmetry that GPT-4o reads off the image.
Watch TrAssembler sample a CAD model
Llama 3.2 fixes the structure, so the set of parts never changes; TrAssembler moves their numbers from random noise to the final shape. Real sampling runs on three ShapeNet test images.
 Input
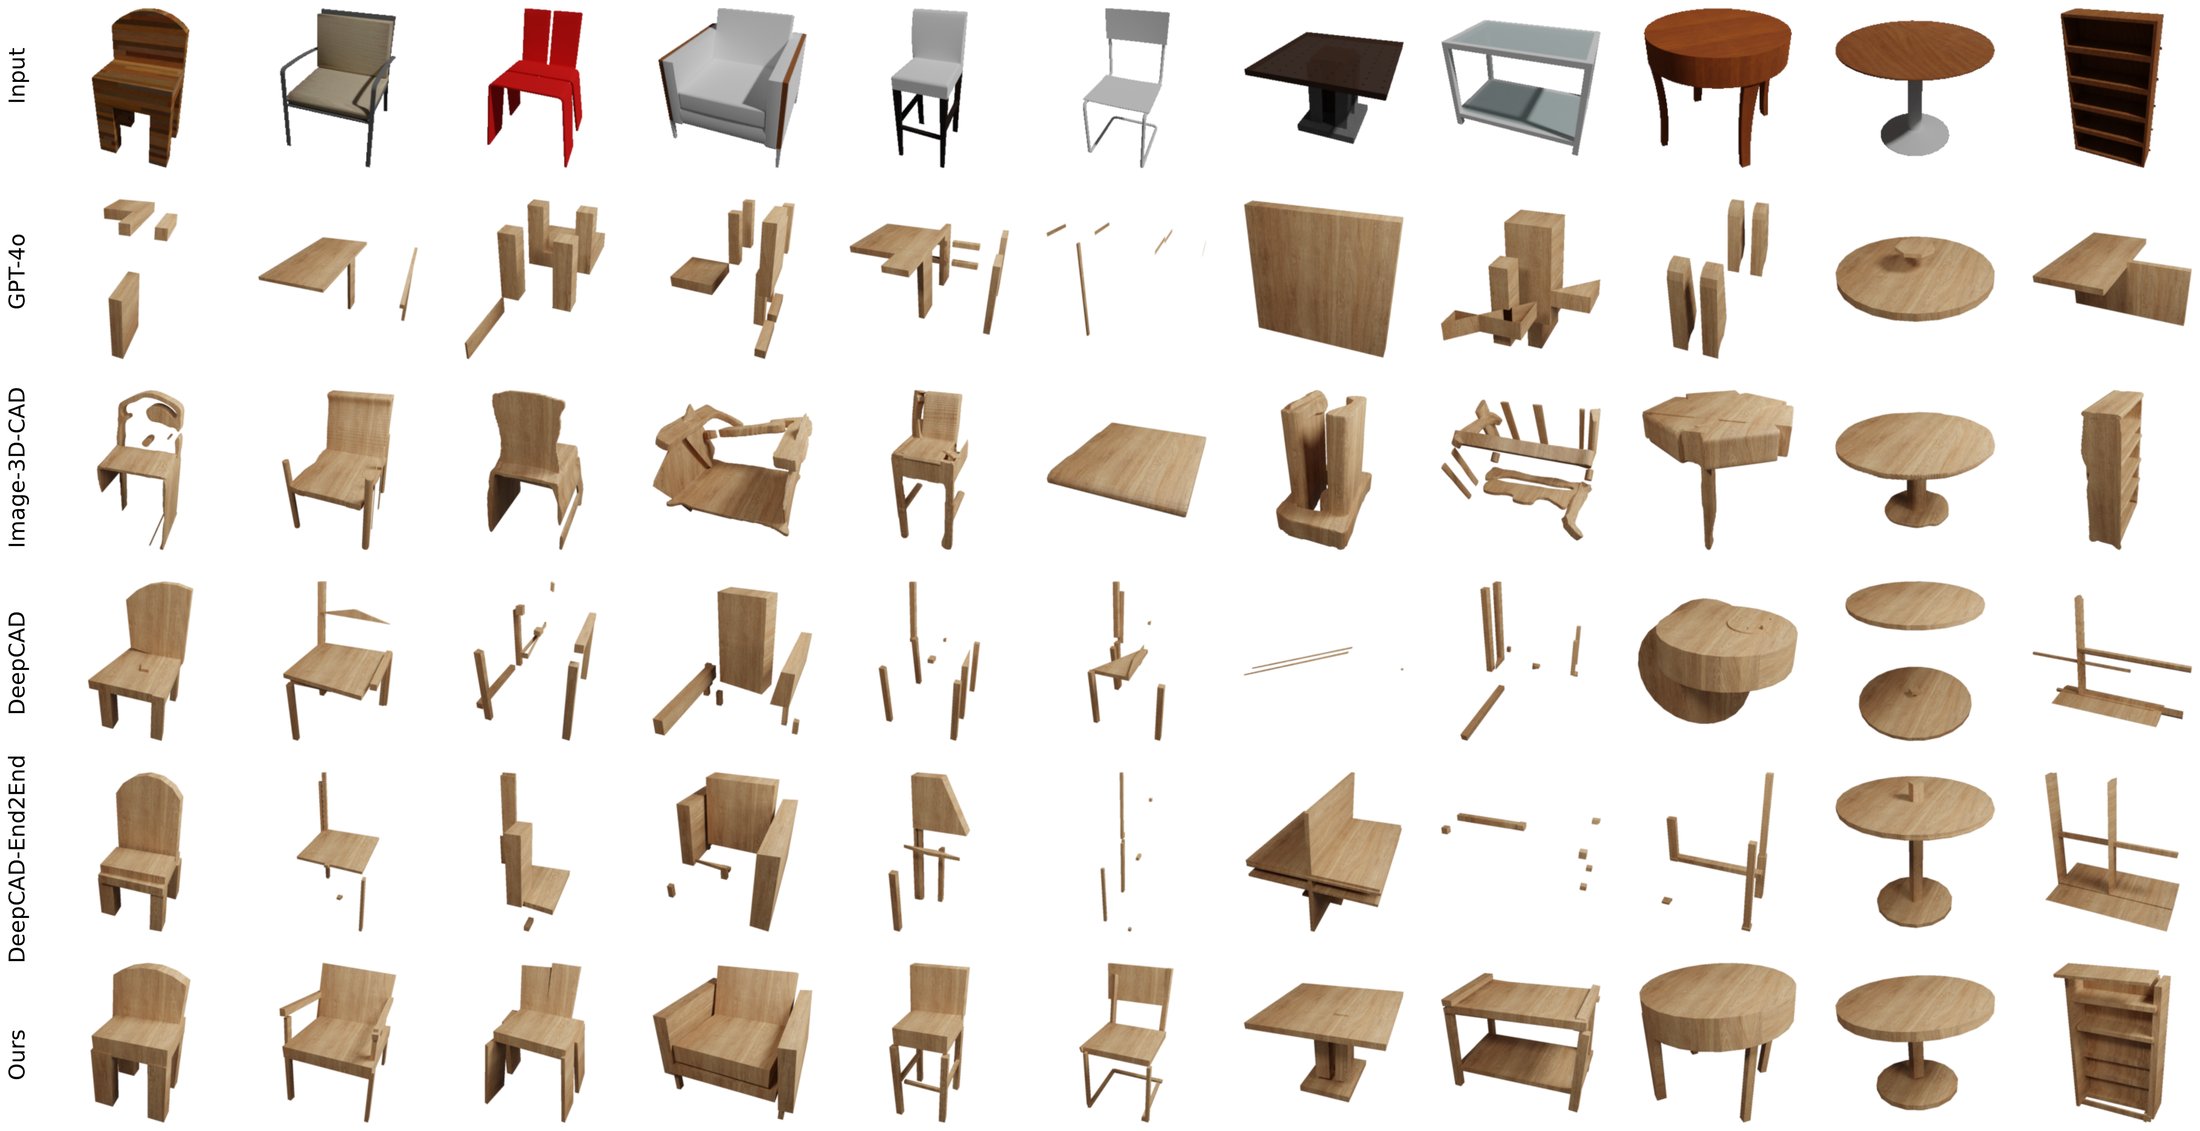
More accurate shapes, with the right parts
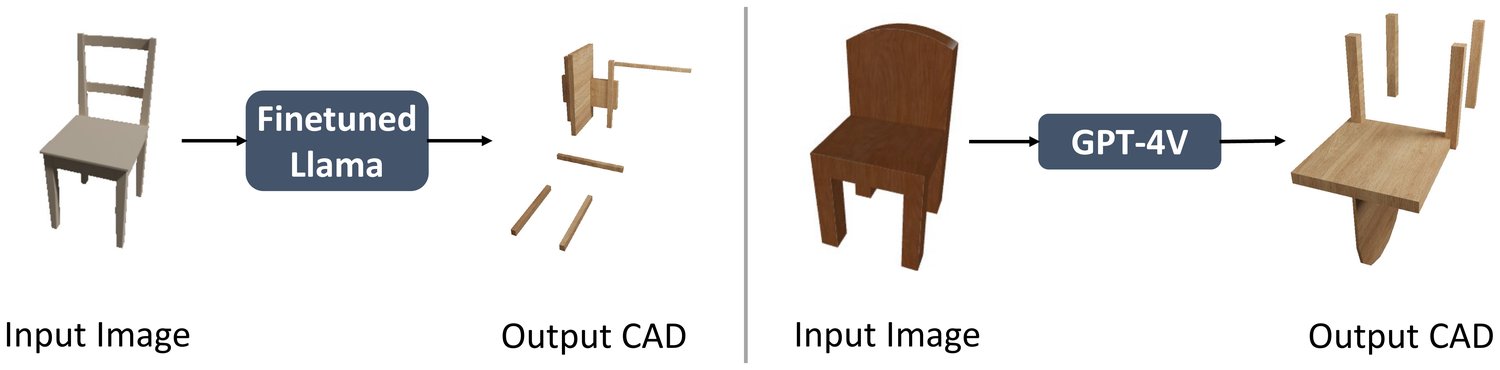
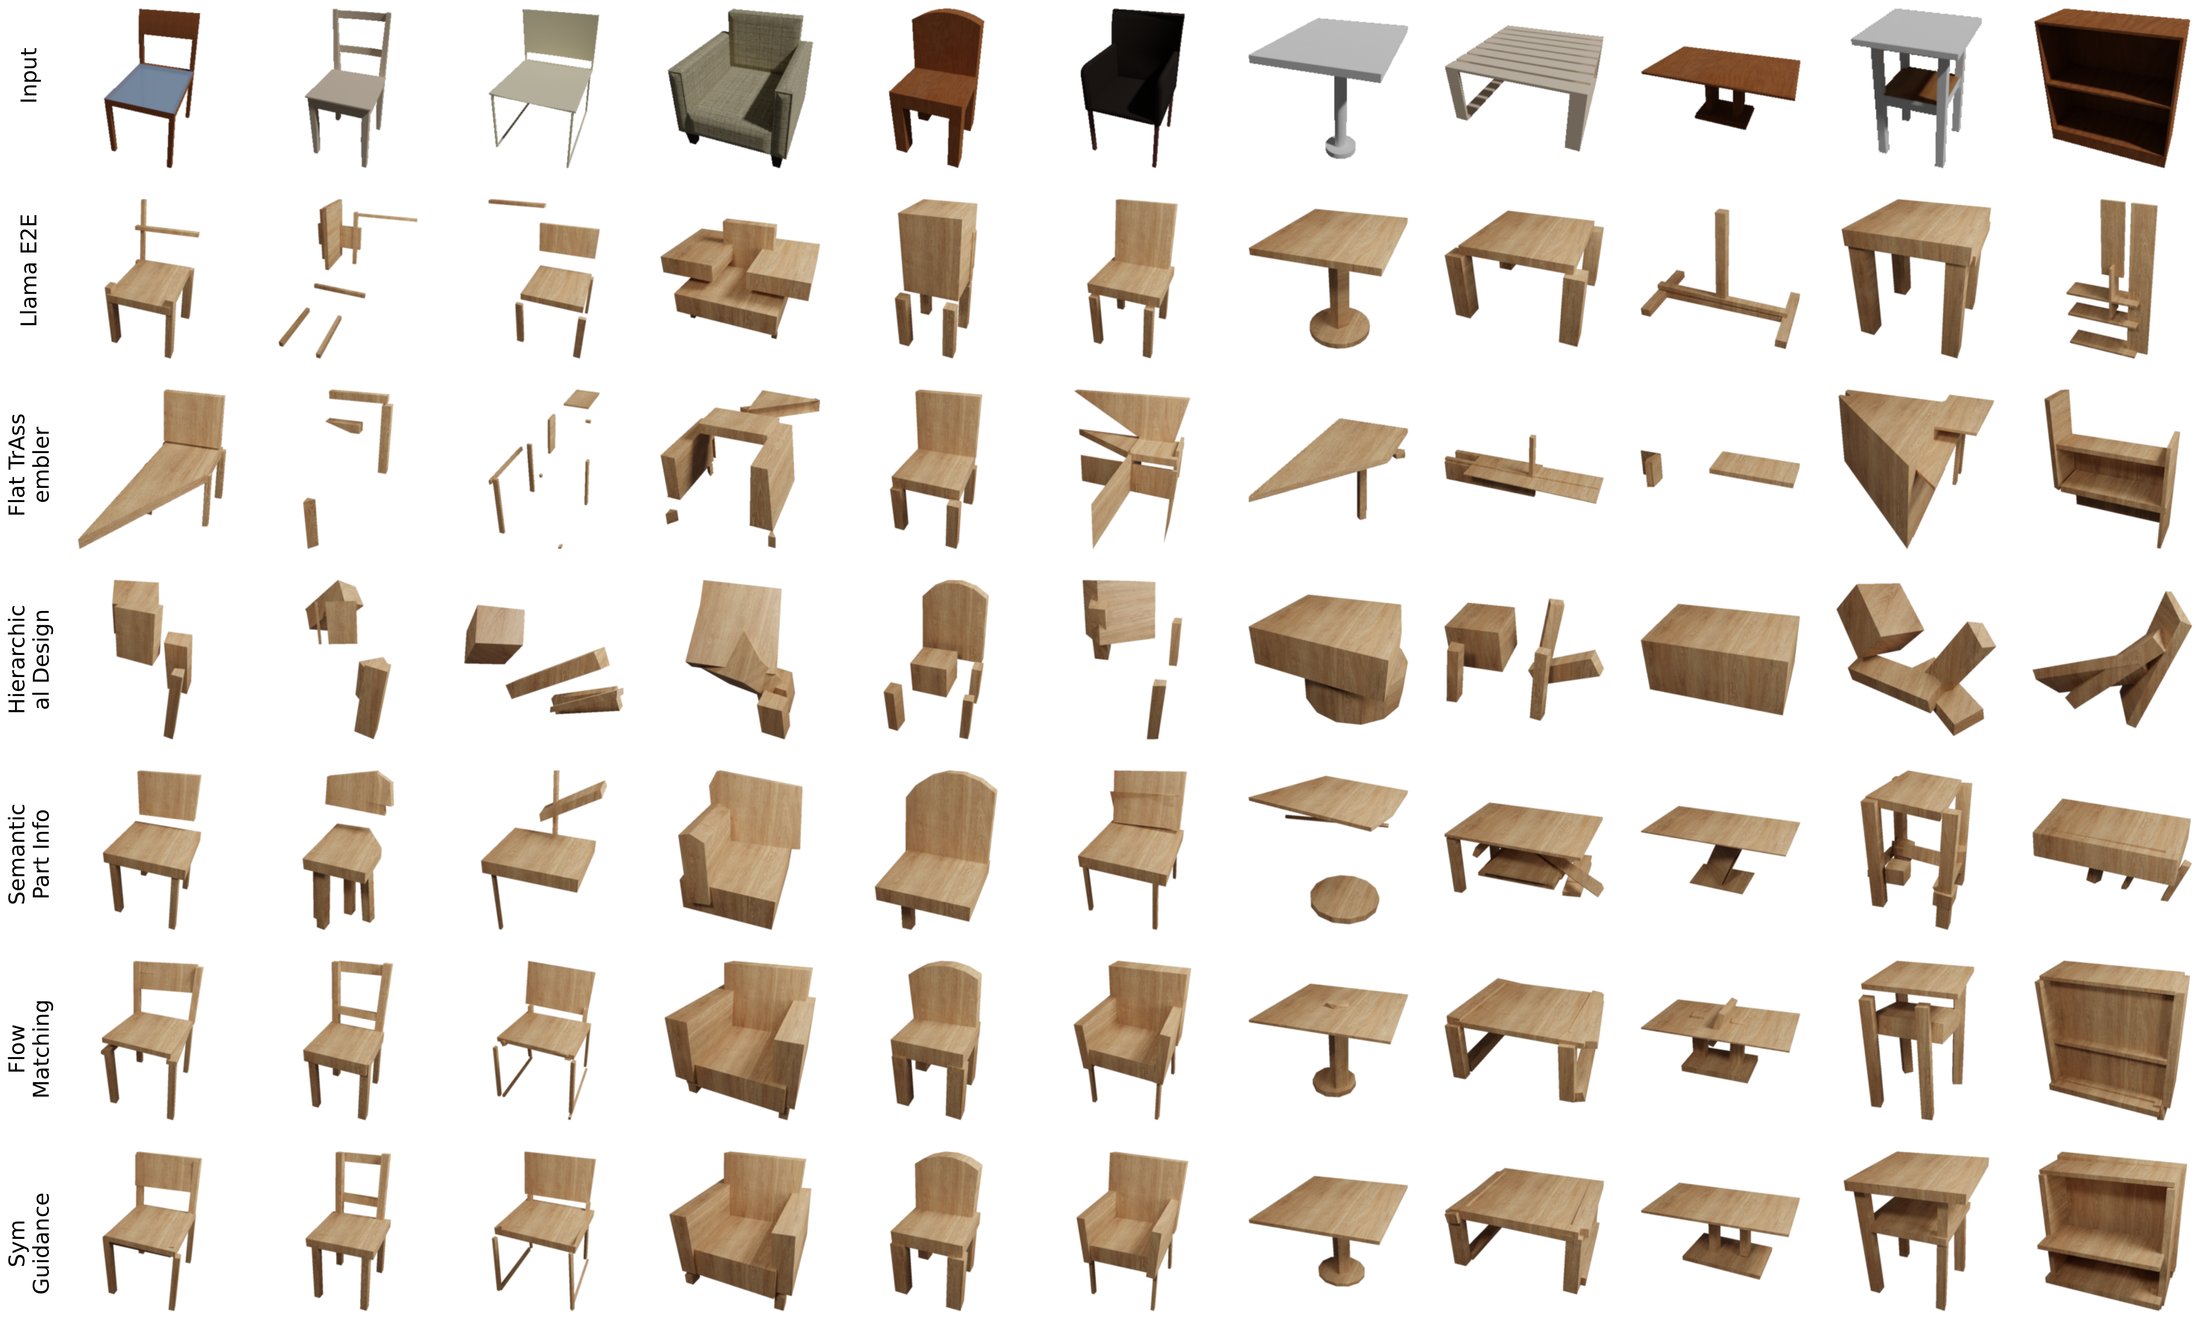
Baselines: GPT-4o writing the whole program; Image-3D-CAD, an image-to-mesh model (LRM) followed by mesh-to-CAD (SECAD-Net); and DeepCAD finetuned on our data, with an image encoder aligned afterwards or trained end to end. Chamfer distance (CD) measures geometry; part segmentation of the output (accuracy and mIoU, %) checks that parts are where they should be.
All numbers
| Method | Chair | Table | Cabinet | ||||||
|---|---|---|---|---|---|---|---|---|---|
| CD ↓ | Seg Acc ↑ | Seg mIoU ↑ | CD ↓ | Seg Acc ↑ | Seg mIoU ↑ | CD ↓ | Seg Acc ↑ | Seg mIoU ↑ | |
| GPT-4o | 0.3806 | 50.49 | 34.96 | 0.3676 | 62.16 | 41.99 | 0.3807 | 54.66 | 47.65 |
| Image-3D-CAD | 0.3266 | 49.03 | 40.73 | 0.3828 | 33.72 | 28.34 | 0.4775 | 59.61 | 49.80 |
| DeepCAD | 0.2914 | 70.44 | 54.86 | 0.3633 | 60.20 | 46.50 | 0.3310 | 62.70 | 54.95 |
| DeepCAD-End2End | 0.2346 | 77.01 | 65.06 | 0.3698 | 67.37 | 52.21 | 0.3279 | 60.55 | 53.23 |
| Img2CAD (ours) | 0.0984 | 91.86 | 87.88 | 0.0966 | 93.81 | 82.13 | 0.1573 | 73.08 | 57.59 |
Turn the results around
Img2CAD's CAD models for ShapeNet test images, and for images rendered from random viewpoints. Pick an input and drag the model.
 Input image
What each part of the design adds
Starting from Llama 3.2 predicting the full program, we add components one at a time; all variants after (i) use the VLM's structure. Semantic part labels and flow matching bring the largest gains; symmetry guidance mostly improves connectivity (fewer disconnected pieces, #SCC) and symmetry (SymChamfer), reported averaged over categories.
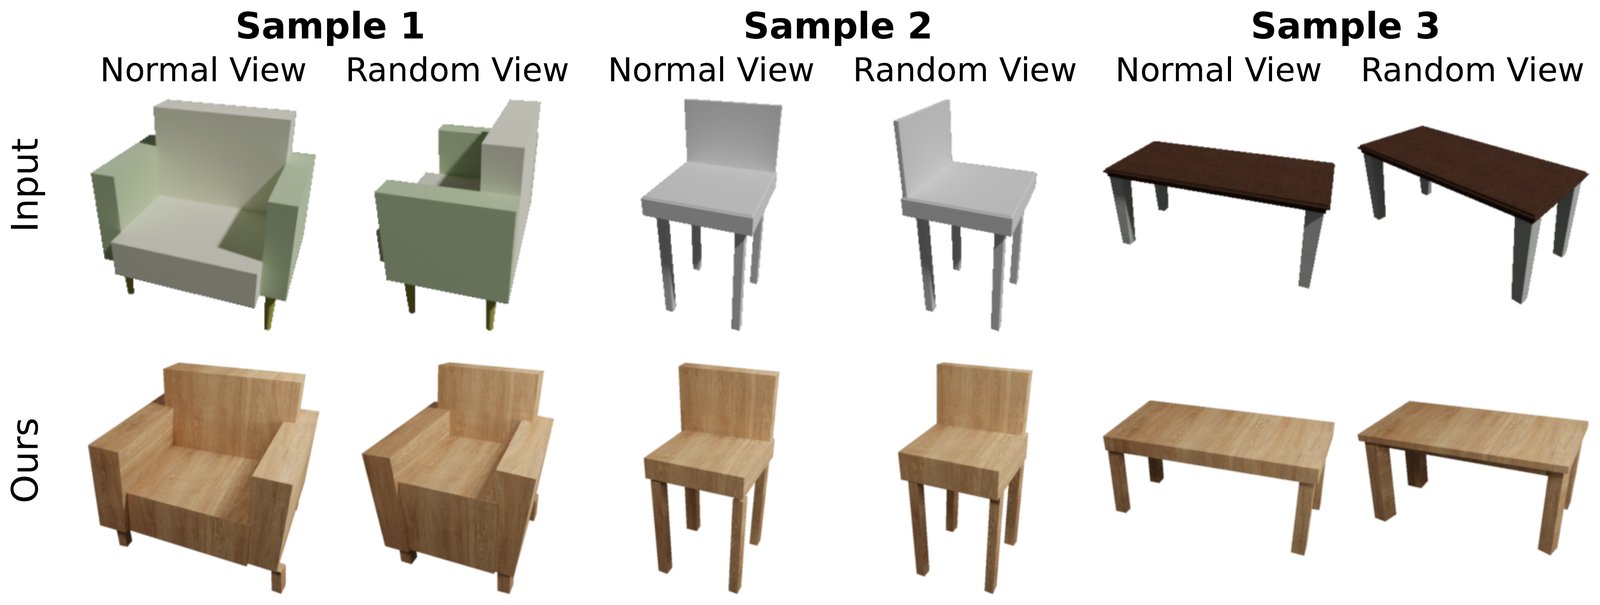
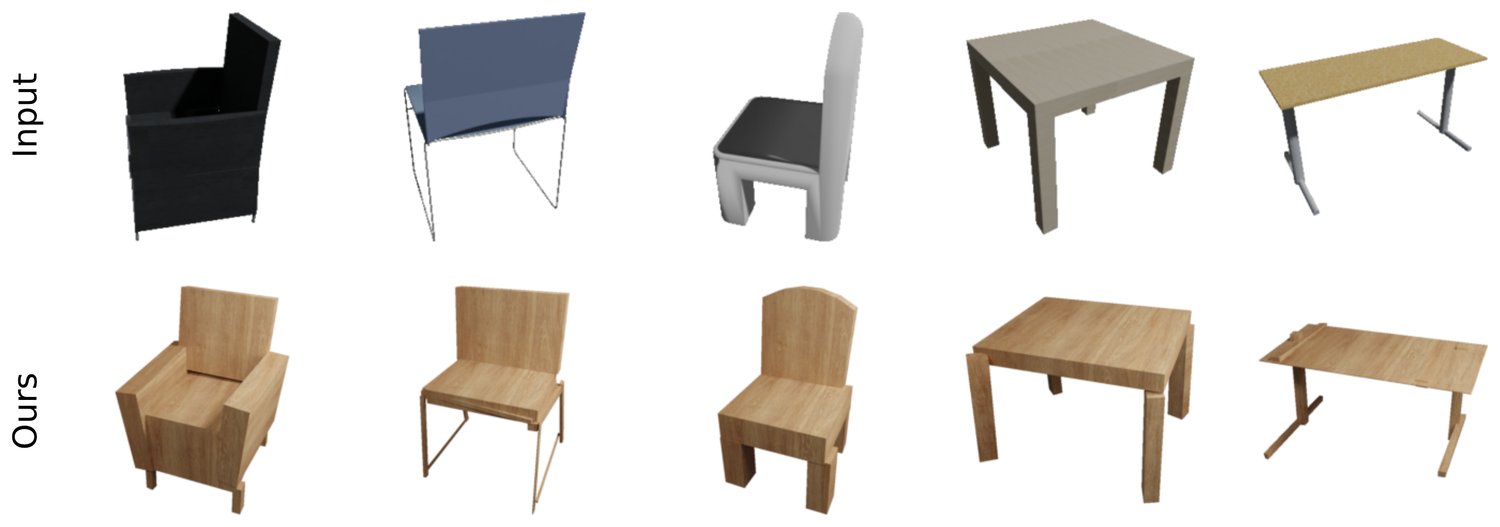
Any viewpoint, and real photos
Trained on renders from a frontal viewpoint, Img2CAD stays accurate on renders from random viewpoints, thanks to the view-robust features of Llama, DINOv2 and CLIP. Averaged over the three categories, frontal → random view:
Chamfer distance
part-segmentation accuracy (%)
part-segmentation mIoU (%)
The CAD models of the same object from a frontal and from a random view are only 0.0282 apart in Chamfer distance.
Real photos
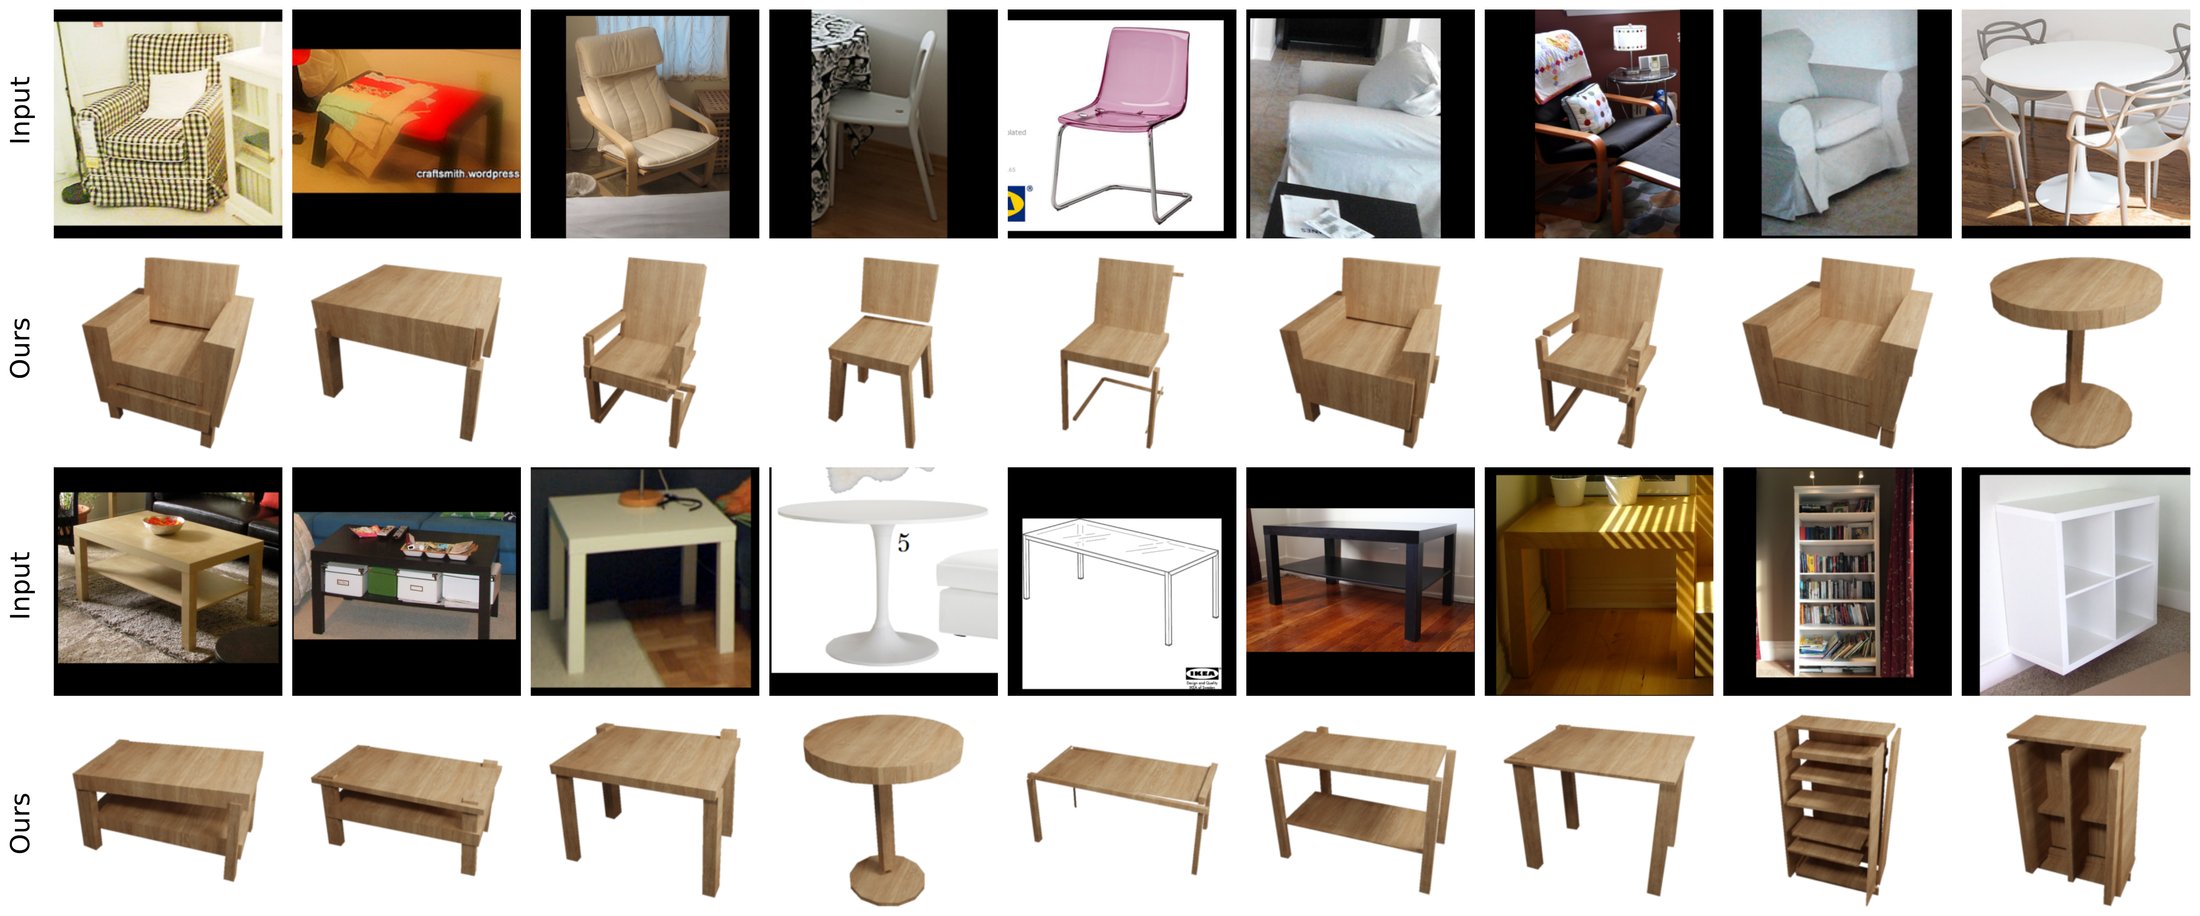
Although TrAssembler is trained only on synthetic, CAD-ified ShapeNet models, Img2CAD also handles real images: indoor photos from Pix3D and product photos of furniture found online.
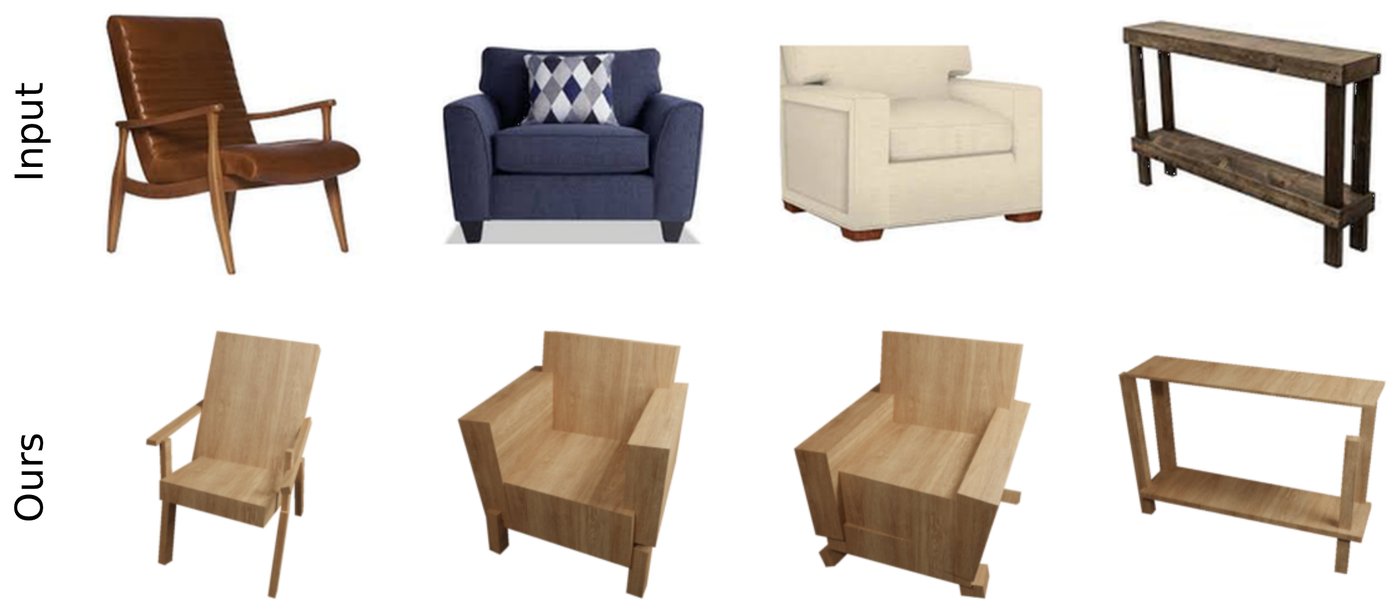
Why it transfers
The structure comes from a VLM trained on web-scale data, and TrAssembler sees the image through DINOv2 and the part names through CLIP. None of these depend on ShapeNet's rendering style, so real photos, with clutter, lighting and occlusion, still produce clean CAD programs.
Edit the CAD model with words
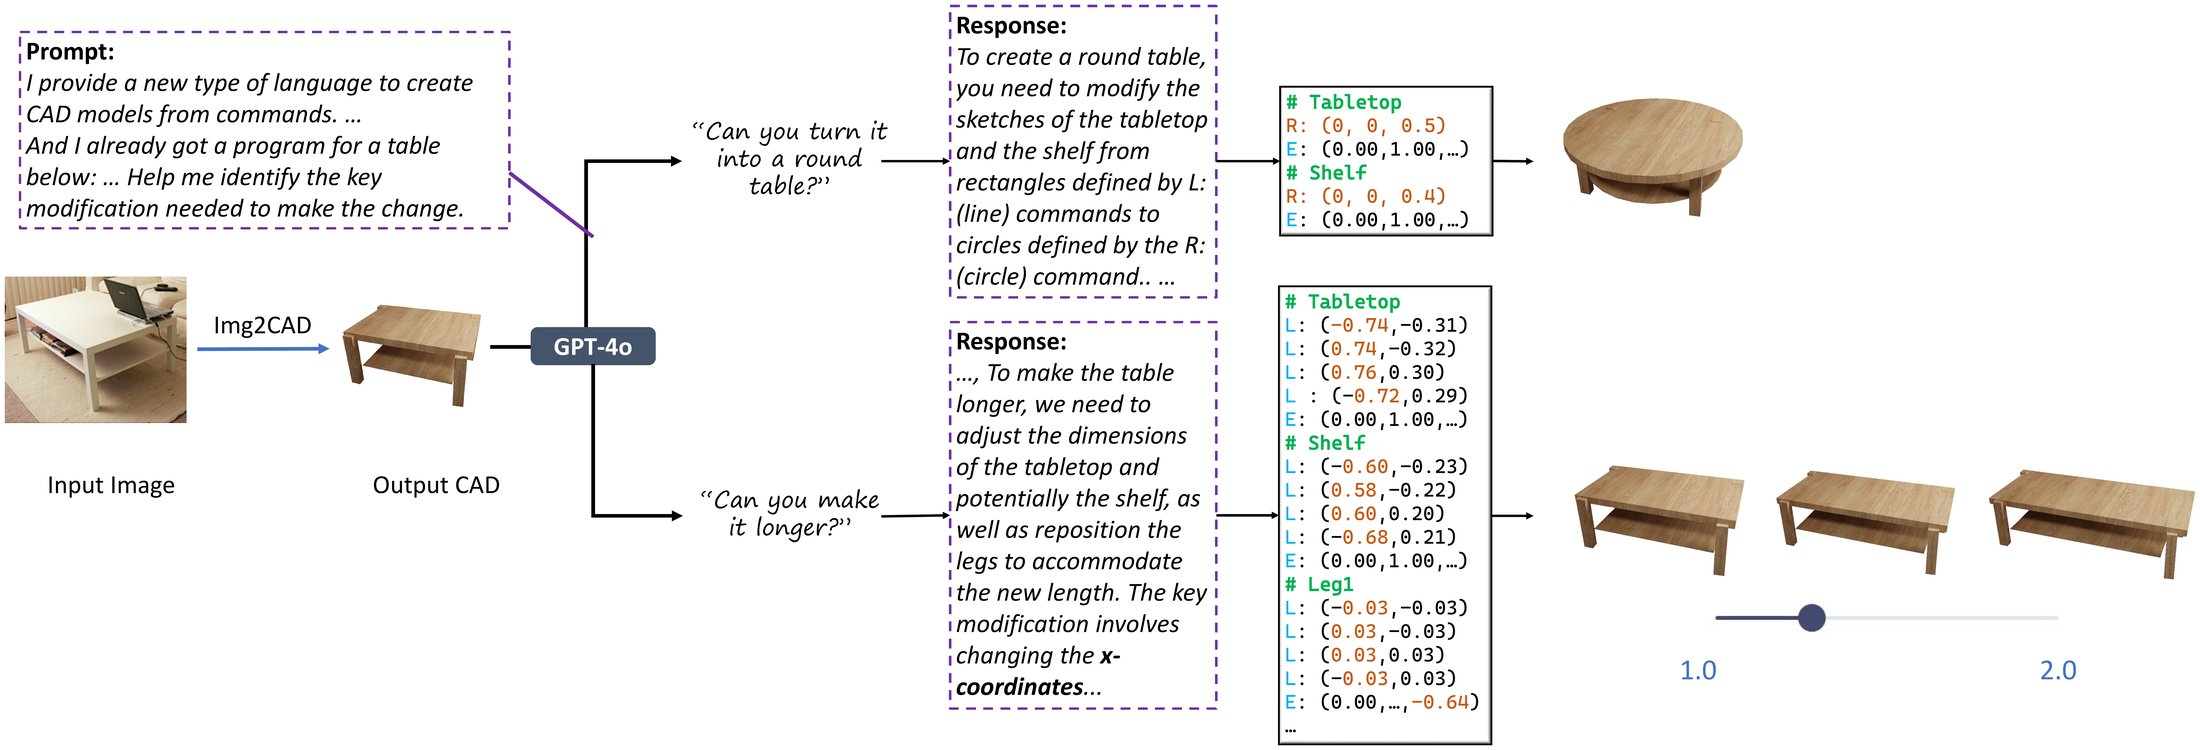
The output is a readable program with named parts, so a language model can edit it. Img2CAD recovers the program from a photo; GPT-4o is then asked for a change. “Turn it into a round table” changes the structure: the tabletop and shelf sketches go from lines to circles. “Make it longer” changes numbers, and GPT-4o moves the legs along with the tabletop. Try similar edits on the chair above.
Everyday objects as CAD programs
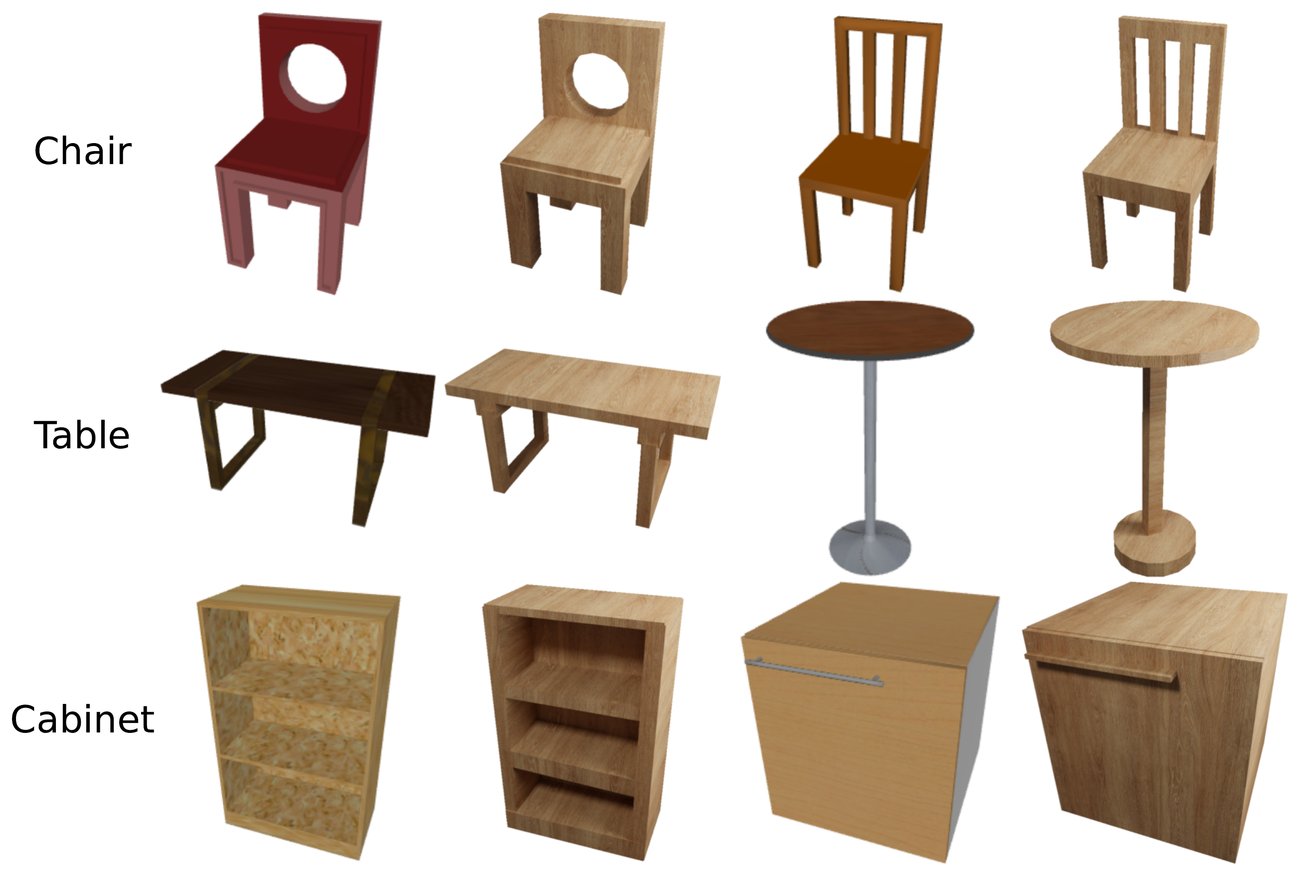
CAD datasets such as ABC are mostly mechanical parts. To train TrAssembler, we turned ShapeNet chairs, tables and cabinets (the categories with PartNet part labels) into sketch-and-extrude programs, semi-automatically:
- GPT-4V draftsFor a render with one part highlighted, GPT-4V writes the part's name and its lines, arcs and circles.
- Matched and fixedIts parts are matched to PartNet's (linear assignment), and their scale and position are corrected.
- Checked by handEvery model is reviewed; about 30% are kept. Splits follow PartNet.
chairs
tables
cabinets
Where it still fails
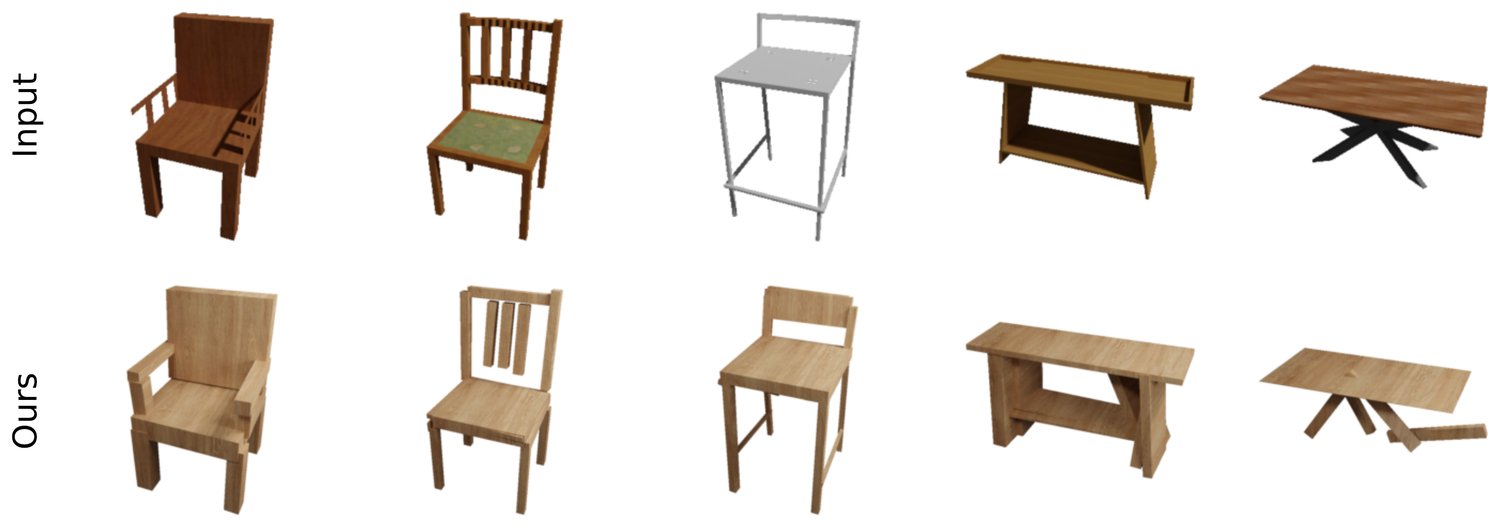
- Structure errors. Llama 3.2 sometimes misses or invents parts. With the ground-truth structure instead, Chamfer distance drops from 0.1174 to 0.1032.
- Rare shapes. TrAssembler can misplace parts on complex, long-tail designs.
- Soft symmetry. Symmetry guidance nudges the numbers, so symmetry and connectivity improve but are not guaranteed.
- Speed. Sampling with 32 Euler steps takes about 5 seconds per shape.
Run it, train it
- Code: finetuning and inference for Llama 3.2 (structure), training and evaluation for TrAssembler.
- Models: Llama adapters, TrAssembler and part-segmentation checkpoints for chairs, tables and storage furniture.
- Dataset: the CAD programs, renders, splits and symmetry labels (also on Google Drive, see the README).
git clone --recursive https://github.com/qq456cvb/Img2CAD.git
hf download qq456cvb/img2cad --local-dir data/ckpts/hf
hf download qq456cvb/img2cad-dataset --repo-type dataset --local-dir data
# stage 1: structure from images, with the finetuned Llama
python LlamaFT/infer.py --category chair --split test \
    --out_dir data/output/llamaft_h5/chair
# stage 2: numbers with TrAssembler, then the metrics
python TrAssembler/eval.py --model_dir data/ckpts/trassembler/chair --text_emb_retrieval
Read the full abstract
Reverse engineering 3D computer-aided design (CAD) models from images is an important task for many downstream applications including interactive editing, manufacturing, architecture, robotics, etc. The difficulty of the task lies in vast representational disparities between the CAD output and the image input. CAD models are precise, programmatic constructs that involves sequential operations combining discrete command structure with continuous attributes – making it challenging to learn and optimize in an end-to-end fashion. Concurrently, input images introduce inherent challenges such as photometric variability and sensor noise, complicating the reverse engineering process. In this work, we introduce a novel approach that conditionally factorizes the task into two sub-problems. First, we leverage vision-language foundation models (VLMs), a finetuned Llama3.2, to predict the global discrete base structure with semantic information. Second, we propose TrAssembler that conditioned on the discrete structure with semantics predicts the continuous attribute values. To support the training of our TrAssembler, we further constructed an annotated CAD dataset of common objects from ShapeNet. Putting all together, our approach and data demonstrate significant first steps towards CAD-ifying images in the wild.
BibTeX
@inproceedings{you2025img2cad,
  title={Img2CAD: Reverse Engineering 3D CAD Models from Images through VLM-Assisted Conditional Factorization},
  author={You, Yang and Uy, Mikaela Angelina and Han, Jiaqi and Thomas, Rahul and Zhang, Haotong and Du, Yi and Chen, Hansheng and Engelmann, Francis and You, Suya and Guibas, Leonidas},
  booktitle={Proceedings of the SIGGRAPH Asia 2025 Conference Papers},
  pages={1--12},
  year={2025},
  doi={10.1145/3757377.3763891}
}