9D pose of unseen objects, learned from synthetic models alone
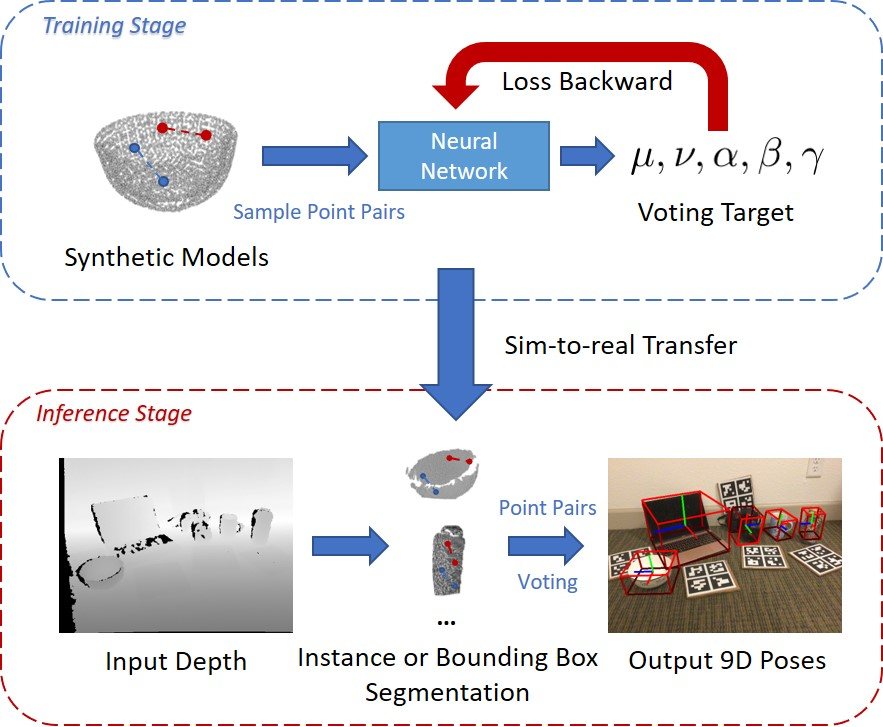
CPPF estimates the 9D pose (3D position, orientation and size) of objects it has never seen, from a single RGB-D frame. Instead of regressing the pose, it lets thousands of point pairs vote for the object's center, orientation and size, using features that do not change when the object moves. Trained only on synthetic ShapeNet models, with no real images or pose labels, it transfers directly to real scenes.
real pose labels or real images used for training
on NOCS REAL275 at 15° / 5 cm; the best earlier sim-to-real method reaches 26.5
mAP at 10° / 5 cm over the best sim-to-real baseline
voting per image on one GTX 1080 Ti: 171 ms center, 229 ms orientation, 13 ms size
Point pairs vote for the pose
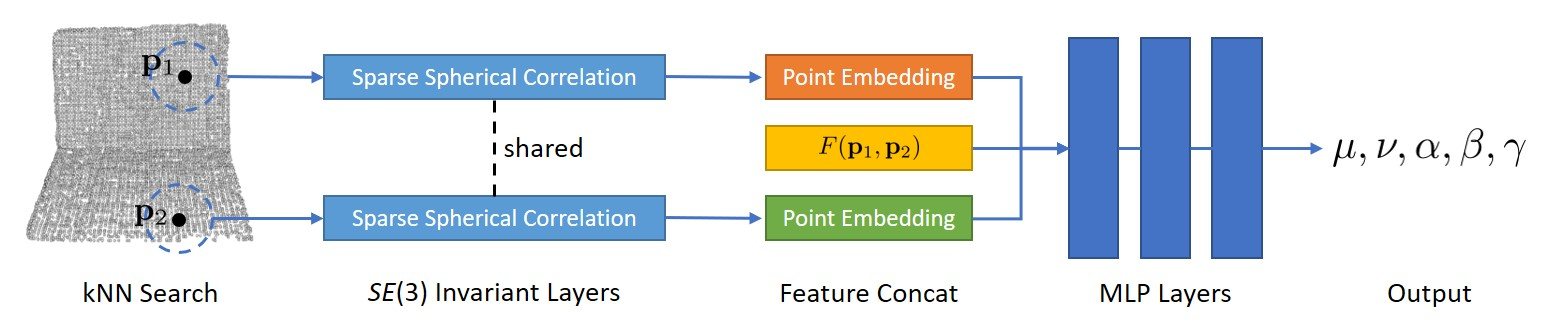
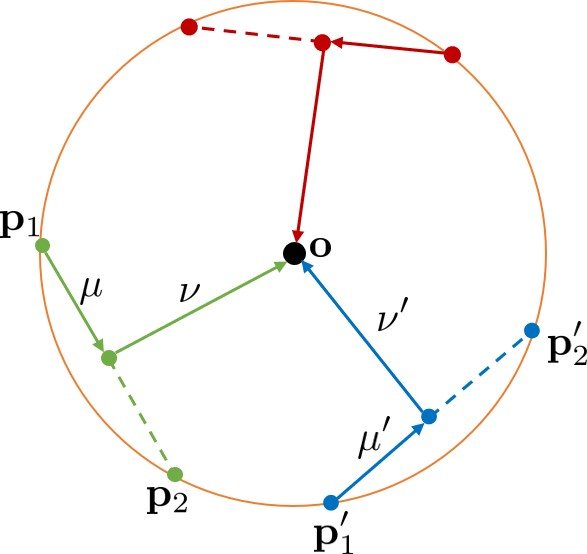
For each pair of points, a network predicts a few numbers that pin down the object's pose up to one degree of freedom. One pair can only say "the center is somewhere on this circle", but thousands of pairs agree on one point. Try it: add pairs and watch the votes pile up.
Vote for
Point pairs
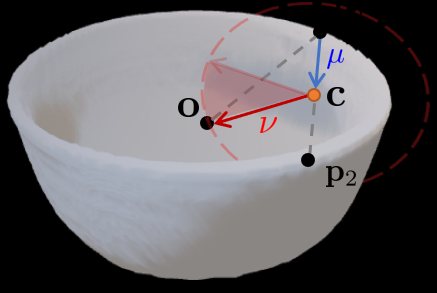
A synthetic bowl with ground-truth voting targets, which the network learns to predict. Drag to rotate.
Invariant targets
Each pair predicts μ, ν (center), α, β (orientation) and a log-size offset. None of them change under rotation or translation, and symmetric objects need no special treatment.
Sign disambiguation
Symmetric shapes also vote for the flipped axis. An auxiliary classifier, which predicts whether each normal faces up or right, picks the right sign.
Coarse-to-fine voting
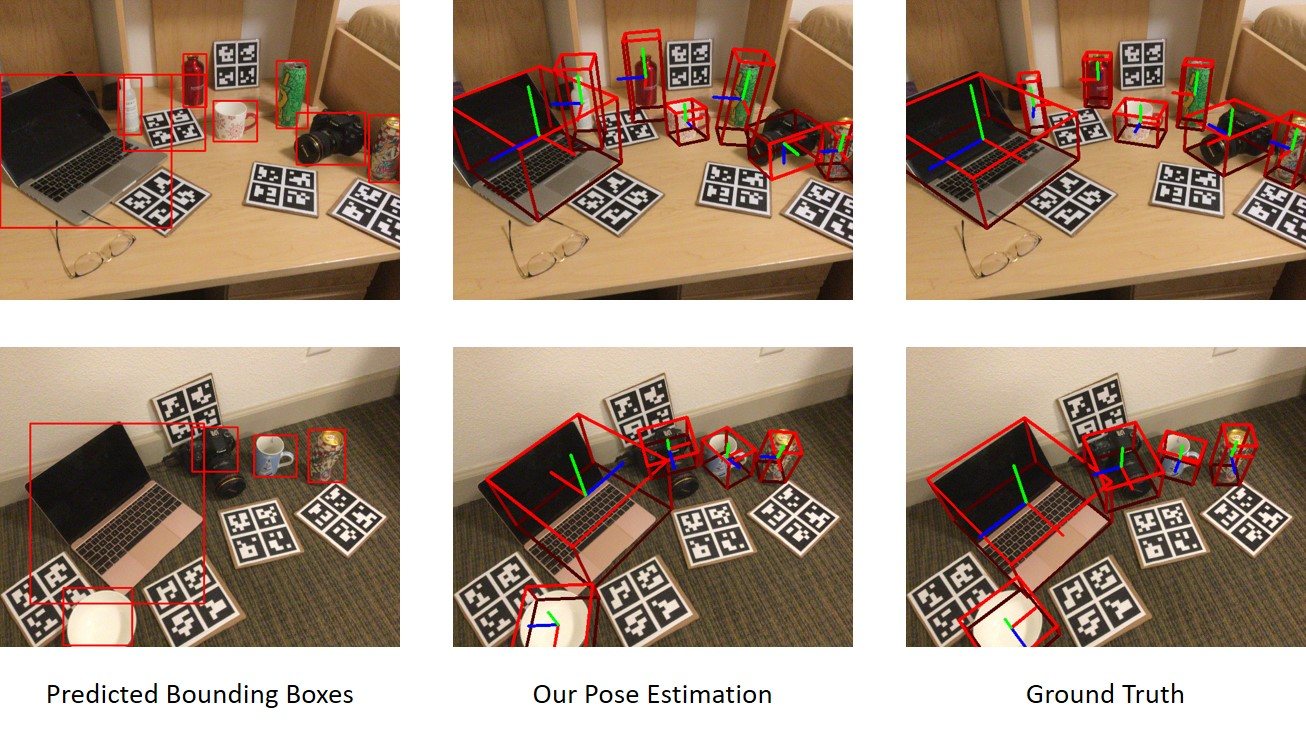
Vote once with all points, keep the points whose votes land near the winning center, and vote again. Inaccurate masks, or even plain bounding boxes, still work.
Sim-to-real by design
Only rendered depth of ShapeNet models with self-occlusion; points are voxelized and jittered on both sides. RGB is used only to tell a laptop's lid from its keyboard.
The best sim-to-real results on REAL275, and robust in the wild
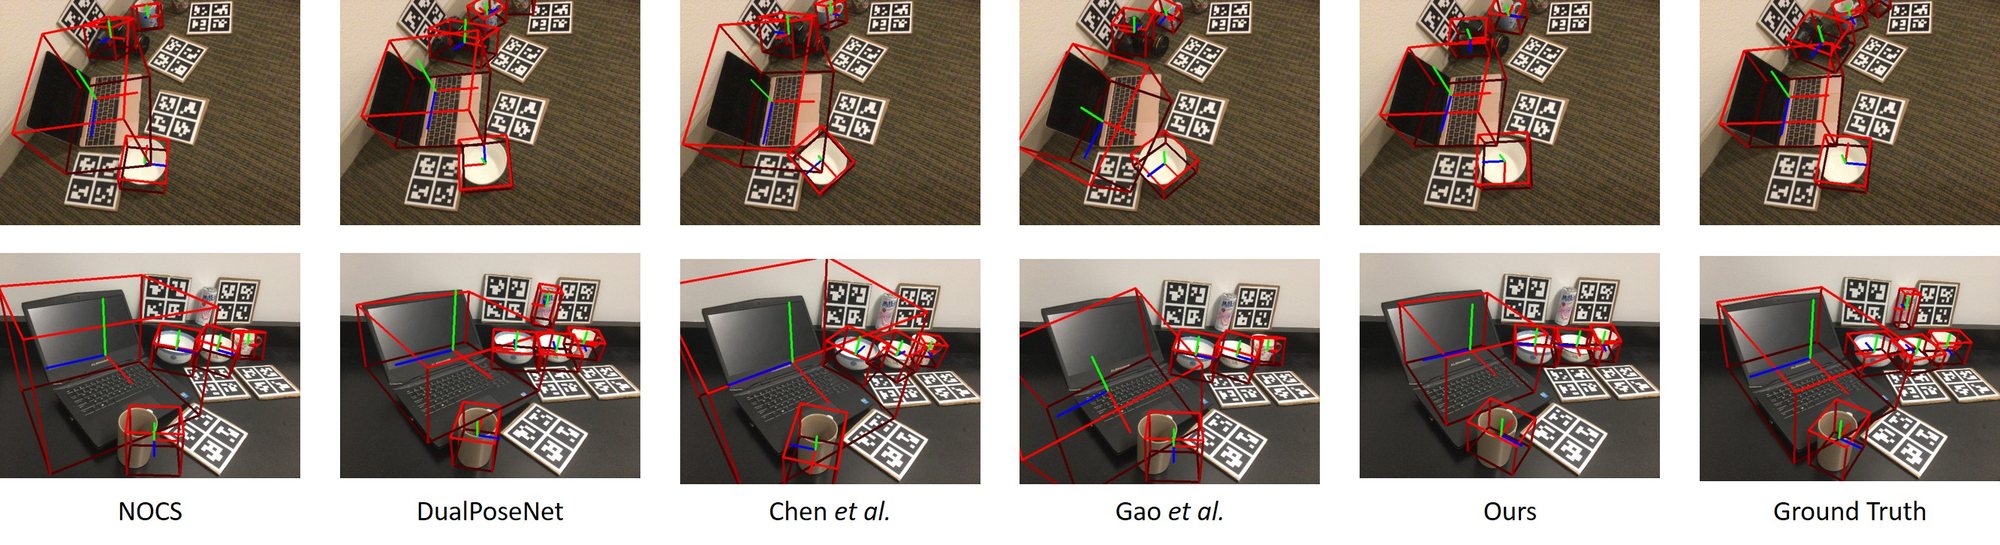
Trained on synthetic ShapeNet models only, and evaluated on real RGB-D frames with the NOCS protocol (mAP over 3D IoU and rotation / translation thresholds).
Without real labels
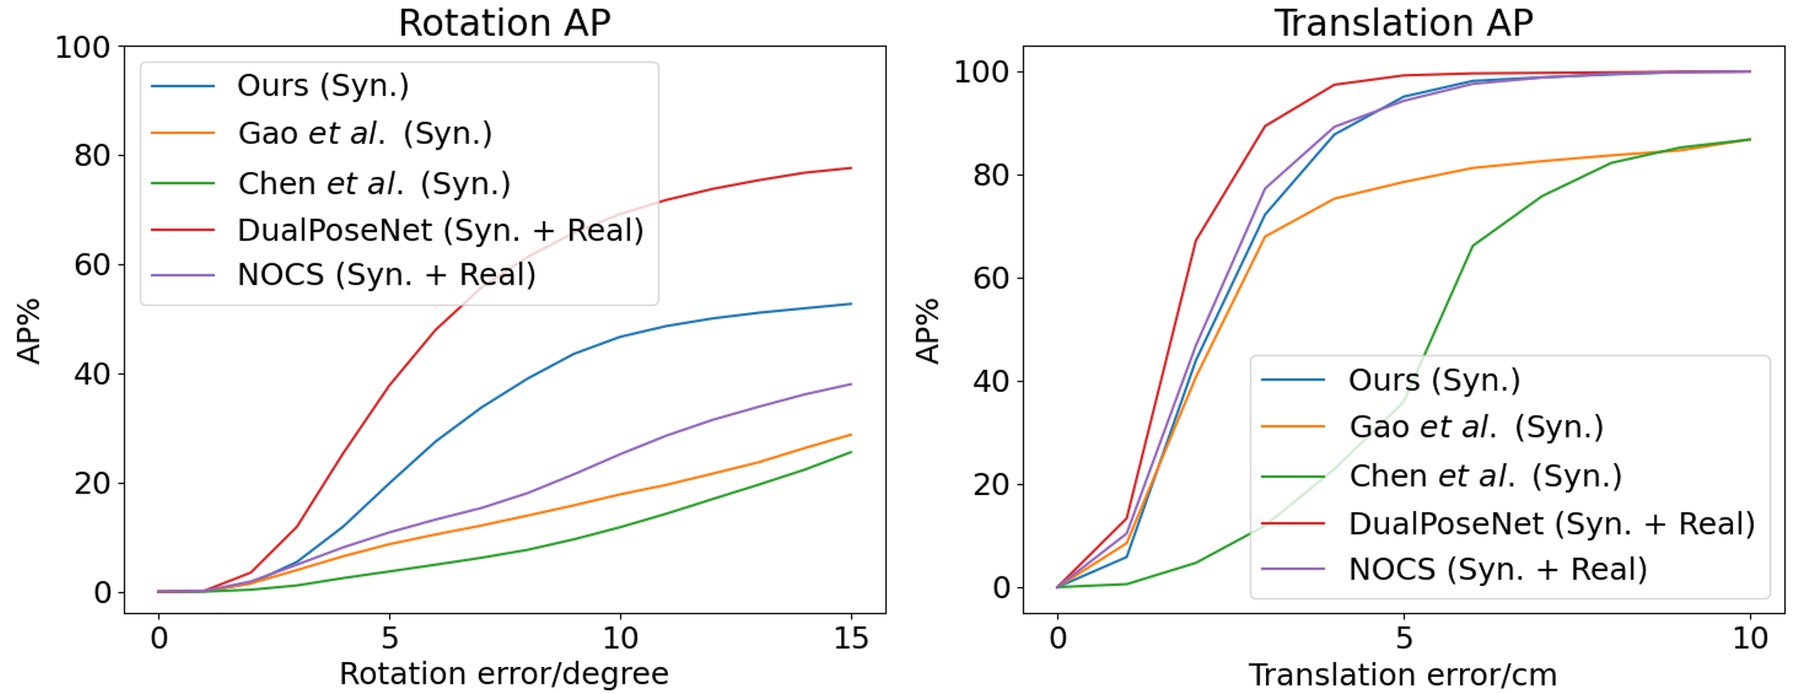
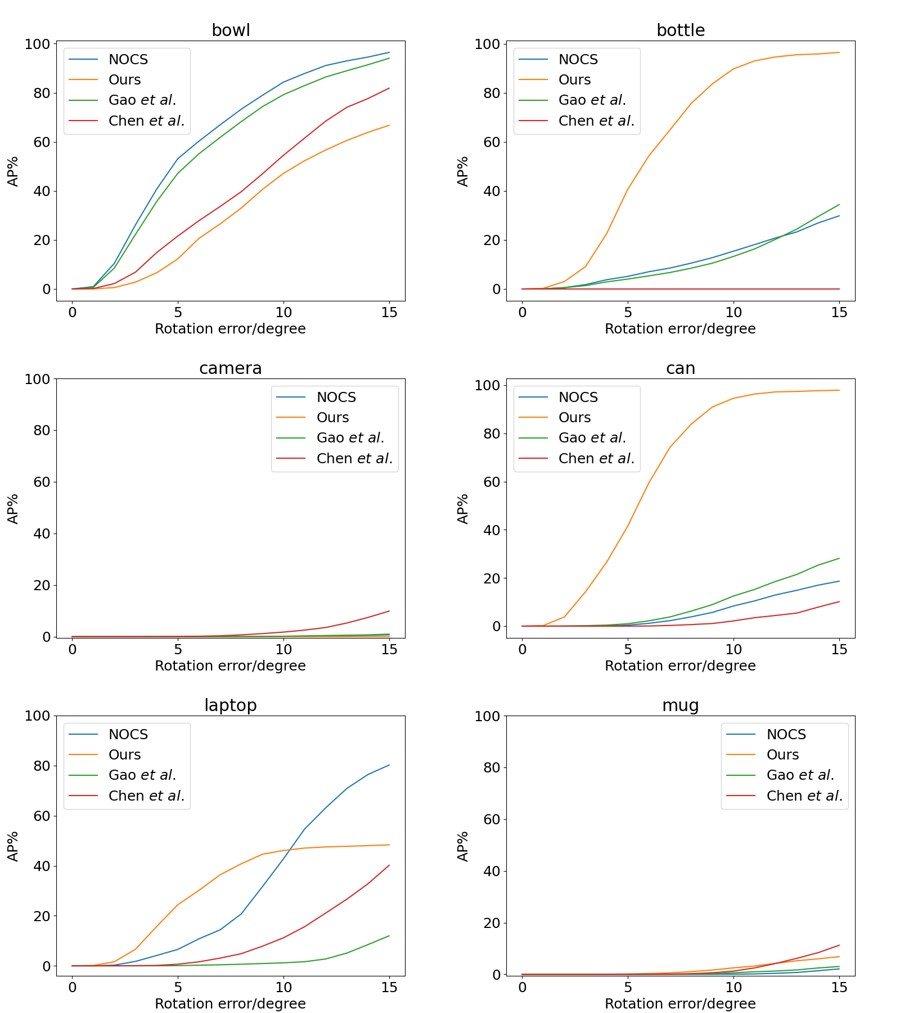
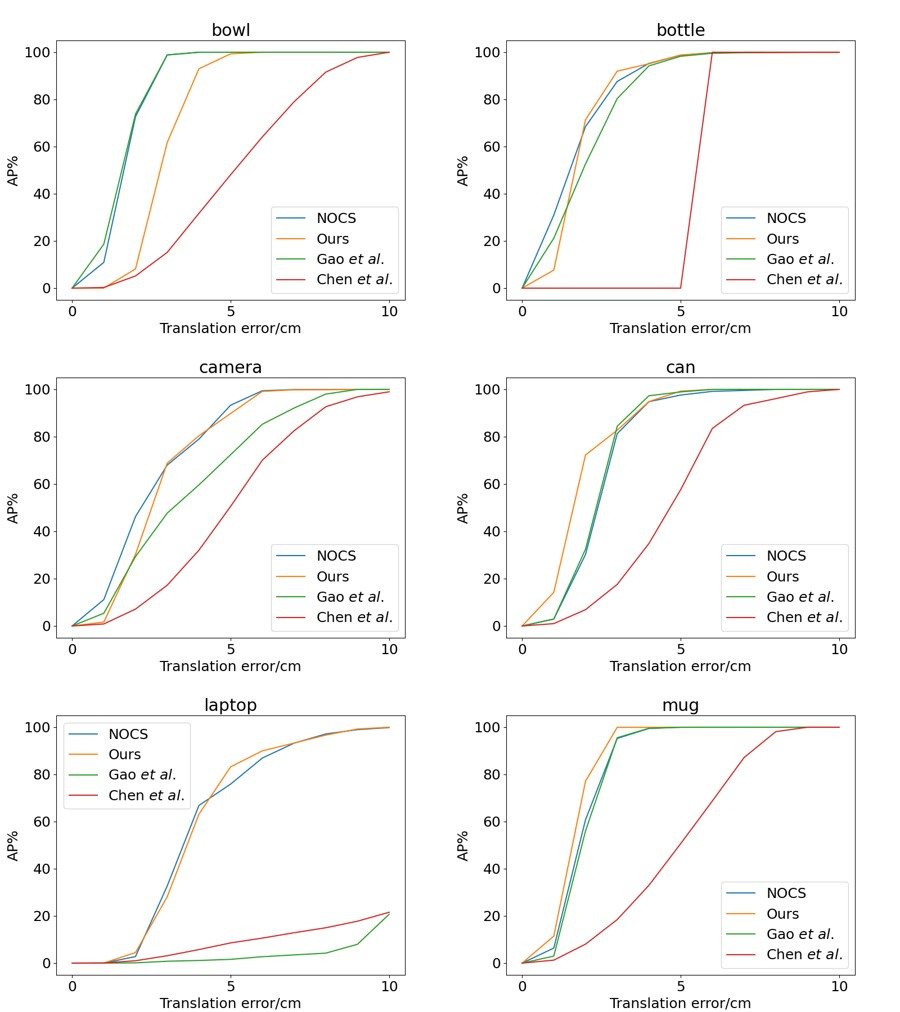
mAP at 5°, 10° and 15° / 5 cm on NOCS REAL275 with instance masks, trained on synthetic objects only.
Over the best sim-to-real baseline
Ahead of Chen et al. and Gao et al. at each of these thresholds, by a wide margin.
Bounding boxes are enough
With only box masks, CPPF still beats NOCS trained with real pose labels (9.8 · 24.1 · 34.9).
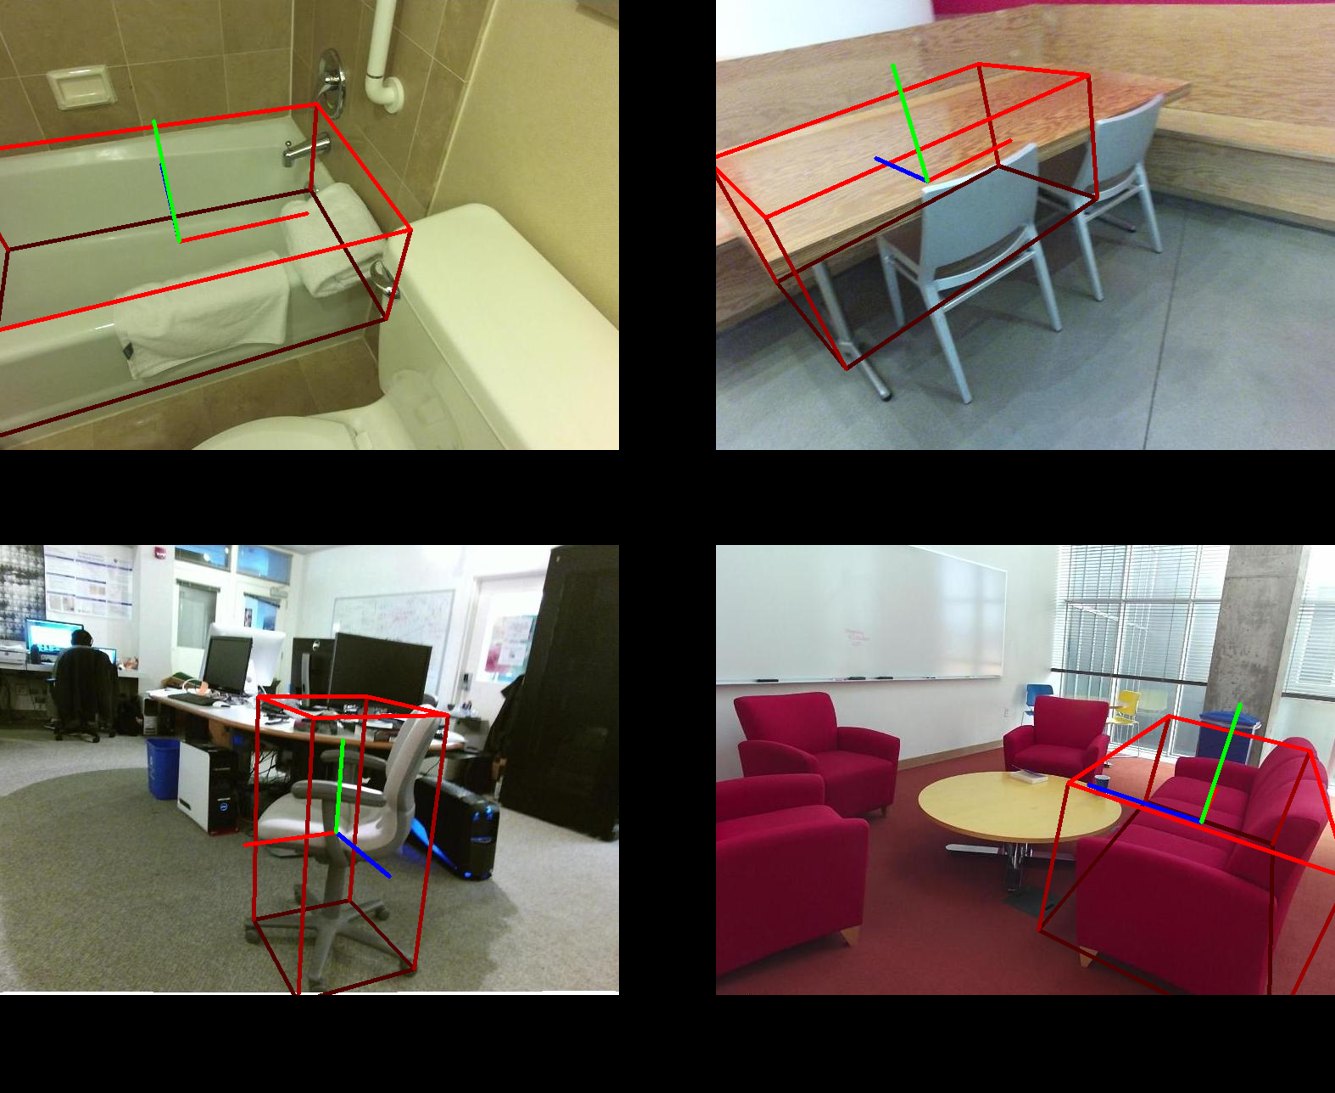
In the wild
mAP at 40° / 20 cm on SUN RGB-D chairs, zero-shot and on randomly rotated scenes, against Gao et al.
| Method | Training data | 3D25 | 3D50 | 5°, 5 cm | 10°, 5 cm | 15°, 5 cm |
|---|---|---|---|---|---|---|
| NOCS | Syn. (O+B) + Real | 74.4 | 27.8 | 9.8 | 24.1 | 34.9 |
| CASS | Syn. (O+B) + Real | – | – | 23.5 | 58.0 | – |
| SPD | Syn. (O+B) + Real | – | – | 21.4 | 54.1 | – |
| FS-Net | Syn. (O+B) + Real | – | – | 28.2 | 60.8 | – |
| DualPoseNet | Syn. (O) + Real | 82.3 | 57.3 | 36.1 | 67.8 | 76.3 |
| Chen et al. | Syn. (O) | 15.5 | 1.3 | 0.7 | 3.6 | 9.1 |
| Gao et al. | Syn. (O) | 68.6 | 24.7 | 7.8 | 17.1 | 26.5 |
| CPPF, bounding-box masks | Syn. (O) | 73.7 | 27.2 | 12.4 | 35.3 | 41.2 |
| CPPF, instance masks | Syn. (O) | 78.2 | 26.4 | 16.9 | 44.9 | 50.8 |
| Method | 3D10 | 3D25 | 20°, 10 cm | 40°, 20 cm | 60°, 30 cm |
|---|---|---|---|---|---|
| Back-projection | 20.2 | 4.4 | 0.0 | 0.6 | 5.8 |
| Gao et al. | 22.2 | 6.0 | 0.0 | 1.0 | 7.0 |
| CPPF | 24.7 | 8.3 | 0.8 | 10.7 | 17.6 |
| Category | 20°, 10 cm | 40°, 20 cm | 60°, 30 cm |
|---|---|---|---|
| Bathtub | 10.9 | 38.8 | 49.8 |
| Bookshelf | 0.0 | 1.0 | 6.4 |
| Bed | 0.0 | 0.8 | 3.4 |
| Sofa | 0.0 | 1.7 | 10.5 |
| Table | 0.5 | 6.9 | 17.5 |
| Variant | 3D25 | 3D50 | 5°, 5 cm | 10°, 5 cm | 15°, 5 cm |
|---|---|---|---|---|---|
| No auxiliary classification | 69.2 | 23.9 | 12.0 | 31.7 | 36.8 |
| No coarse-to-fine voting | 75.6 | 22.3 | 9.7 | 27.4 | 32.6 |
| Regression instead of classification | 73.3 | 14.7 | 1.8 | 12.7 | 24.2 |
| No voxelization | 76.7 | 21.6 | 11.9 | 37.2 | 45.6 |
| No jittering | 77.1 | 24.6 | 16.2 | 43.1 | 49.7 |
| CPPF (full) | 78.2 | 26.4 | 16.9 | 44.9 | 50.8 |
| Point pairs | Orientation bin (°) | 3D25 | 3D50 | 5°, 5 cm | 10°, 5 cm | 15°, 5 cm |
|---|---|---|---|---|---|---|
| 100,000 | 1 | 78.3 | 24.3 | 13.2 | 38.2 | 45.7 |
| 100,000 | 2 | 78.5 | 25.9 | 13.4 | 46.6 | 52.2 |
| 100,000 | 4 | 78.4 | 26.2 | 7.0 | 42.7 | 53.5 |
| 10,000 | 1.5 | 68.5 | 21.7 | 8.6 | 27.2 | 34.1 |
| 60,000 | 1.5 | 78.1 | 25.8 | 15.6 | 42.8 | 49.1 |
| 200,000 | 1.5 | 78.4 | 26.6 | 17.3 | 45.5 | 51.3 |
| 100,000 | 1.5 | 78.2 | 26.4 | 16.9 | 44.9 | 50.8 |
Running time per image on one GTX 1080 Ti: 171 ms for center voting, 229 ms for orientation and 13 ms for size.
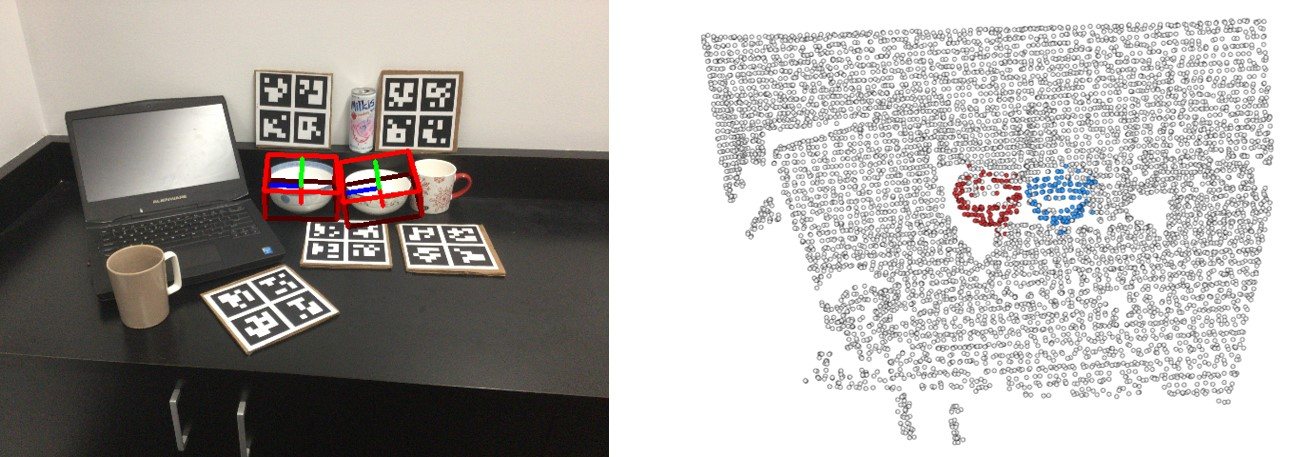
Real scenes, synthetic training
Run it
- Code: training on ShapeNet, evaluation on NOCS REAL275 and SUN RGB-D, and training on your own object categories.
- Models: checkpoints for 12 categories, plus the laptop lid/keyboard segmenter, on Hugging Face.
- Data: detection priors for REAL275 (
nocs_seg.zip), rendered laptop images and prepared SUN RGB-D data. - License: MIT.
git clone https://github.com/qq456cvb/CPPF && cd CPPF
pip install -U "huggingface_hub[cli]"
hf download qq456cvb/CPPF --local-dir checkpoints
# NOCS REAL275 (data setup in the README)
python nocs/inference.py --adaptive_voting
python nocs/eval.py
# bounding-box masks only: add --bbox_mask
Read the full abstract
In this paper, we tackle the problem of category-level 9D pose estimation in the wild, given a single RGB-D frame. Using supervised data of real-world 9D poses is tedious and erroneous, and also fails to generalize to unseen scenarios. Besides, category-level pose estimation requires a method to be able to generalize to unseen objects at test time, which is also challenging. Drawing inspirations from traditional point pair features (PPFs), in this paper, we design a novel Category-level PPF (CPPF) voting method to achieve accurate, robust and generalizable 9D pose estimation in the wild. To obtain robust pose estimation, we sample numerous point pairs on an object, and for each pair our model predicts necessary SE(3)-invariant voting statistics on object centers, orientations and scales. A novel coarse-to-fine voting algorithm is proposed to eliminate noisy point pair samples and generate final predictions from the population. To get rid of false positives in the orientation voting process, an auxiliary binary disambiguating classification task is introduced for each sampled point pair. In order to detect objects in the wild, we carefully design our sim-to-real pipeline by training on synthetic point clouds only, unless objects have ambiguous poses in geometry. Under this circumstance, color information is leveraged to disambiguate these poses. Results on standard benchmarks show that our method is on par with current state of the arts with real-world training data. Extensive experiments further show that our method is robust to noise and gives promising results under extremely challenging scenarios.
BibTeX
@inproceedings{you2022cppf,
  title={CPPF: Towards Robust Category-Level 9D Pose Estimation in the Wild},
  author={You, Yang and Shi, Ruoxi and Wang, Weiming and Lu, Cewu},
  booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
  pages={6866--6875},
  year={2022}
}